

In This Article
Knowing what PerplexityBot and Perplexity-User do is half the job. The other half is knowing what to fix on one specific page. This article is the page-level workflow: a seven-block template you can run against any URL, and how NovaX shows you which block is failing.
In How to Optimize Your Website for Perplexity I covered what Perplexity documents: which crawler does what, how the answer engine builds a response, and which popular claims have no evidence behind them. I will not repeat that here. This article asks a narrower question. Given a single page, what do you look at, in what order, and how do you know afterwards whether anything changed?
I use NovaX for that. It scores each page against engine-specific signals, one engine at a time. For Perplexity, it models one particular idea: that the engine behaves like a real-time retrieval system that wants fast, dense, extractable facts and has little patience for narrative. That model is useful, and it is also a model, not a view inside Perplexity. I keep the two apart throughout, and the section on evidence levels says exactly where the line sits.
What is in This Series
This article is part of the cluster How to Measure Your Presence in AI Search Engines. The hub also contains AI Search Visibility Share of Voice, and a pair of articles for each engine:
- – ChatGPT: Official guide, How to measure and How to optimize with NovaX
- – Perplexity: Official guide, How to measure and How to optimize with NovaX
- – Claude: Official guide, How to measure and How to optimize with NovaX
- – Gemini: Official guide, How to measure and How to optimize with NovaX
- – Copilot: Official guide and How to measure
- – Grok: Official guide and How to measure
- 1. The official guide articles say what the engine’s owner documents.
- 2. The measure articles say how to track presence over time.
- 3. The How to optimize with NovaX sits between them: it is the hands-on step where you inspect a page and decide what to change.
What the Perplexity Engine Is?
Perplexity is the speed and fact-density engine: it asks whether the answer is where a retriever will find it, whether it is in a form that can be lifted out, and whether it is stated as fact. Those are the three questions the engine profile is built around, and every signal in the report maps to one of them.
- – Is the answer easy to find? Does the exact answer to the target query appear in the first paragraphs, or is it buried under an introduction?
- – Is it easy to lift? Are the key facts in clean tables and lists, with valid schema and a clear heading structure around them?
- – Is it stated as fact? Is the content made of definite, checkable statements, or of marketing filler a retriever has to read past?
The NovaX description of the engine is a real-time retrieval-augmented generation (RAG) system that pulls live sources to answer a query. Perplexity describes itself in similar terms: an answer engine that searches the live web and shows numbered source links. That part is consistent. The three questions above are NovaX’s way of turning “instant factual extraction” into things a crawler can check on a page, and Perplexity does not publish them as criteria.
Two points of scope matter before you read any score. First, “Perplexity” covers its default search, Pro search and the Research mode, and they can retrieve differently. The NovaX engine profile scores page-level signals that are relevant to retrieval in general. It does not tell you which mode cited you, and it cannot see your firewall rules or your CDN settings. The access checks in Step 1 of the Perplexity optimize article still have to be done by a person.
Second, the profile has an opinion about length that differs from the ChatGPT one. It says Perplexity cares less about long-form narrative and more about instant factual extraction. I read that as a statement about how a page is arranged, not as permission to write thin pages. A long page can pass every Perplexity check if the answer is at the top and the facts are in tables.
How to Read the NovaX Perplexity Report
Read two numbers first, then the signals underneath them, and never act on the headline alone. A Perplexity report opens with an Engine Score out of 100 and a Citation Probability as a percentage. They answer different questions, and they can disagree.
- – Engine Score: how completely the page’s signals match what the Perplexity profile looks for. The report adds a score trend, and a comparison with your workspace average once you have inspected more pages.
- – Citation Probability: a more cautious eligibility estimate. In the report I am using as the example, a page scored 89 out of 100 and 68% citation probability, and NovaX labelled that “strong citation eligibility”.
Those two are not the same. A page can match the profile well and still be a middling bet to be cited, because a retrieval system chooses among competing pages and the choice depends on more than the page. When the two diverge, open the detail before you celebrate either number. In this report the gap had a specific, named cause, which the worked example below covers.
The engine weights its score in four parts:
| Component | Weight | What it covers for Perplexity |
|---|---|---|
| Schema and metadata | 35% | JSON-LD, with Article, FAQ and HowTo types treated as direct citation eligibility signals |
| Extractability | 28% | Lists, tables, structured paragraphs and FAQ markup that let a retriever pull a clean answer |
| Freshness | 20% | dateModified and content age, because real-time retrieval skips stale pages |
| Structural integrity | 17% | A single H1 and a logical heading hierarchy, for topic extraction and citation boundaries |
The report also scores entity clarity as a fifth core signal, which sits beside these four without a listed weight for Perplexity. I read it as supporting context, and not as something that drives the score.
The tabs then split the page into parts you can act on:
| Tab | What it tells you | What you do with it |
|---|---|---|
| Overview | Score, trend, citation probability, top actions, issues, engine-specific checks | Decide where to start |
| Signals | The five core signals scored individually | Find the weakest block of the template |
| Simulator | Projected score impact of each fix | Order fixes by payoff before you touch the page |
| Queries | The questions found on the page and how eligible each is | Spot weak or noisy question headings |
| Entities | Entities detected, their type, schema status and clarity | Decide which entities need clearer definition |
| Recommendations | Specific issues raised by the Inspector | Fix the cheap, concrete ones |
| Freshness | Freshness score and sensitivity for the engine | Decide whether the page is due an honest update |
The Simulator is the part I use most. You tick the fixes you plan to make and it projects the score change, so you can see in advance whether a fix is worth an hour. In the example report, adding dateModified to the JSON-LD was projected at +10, the largest single item on the list.
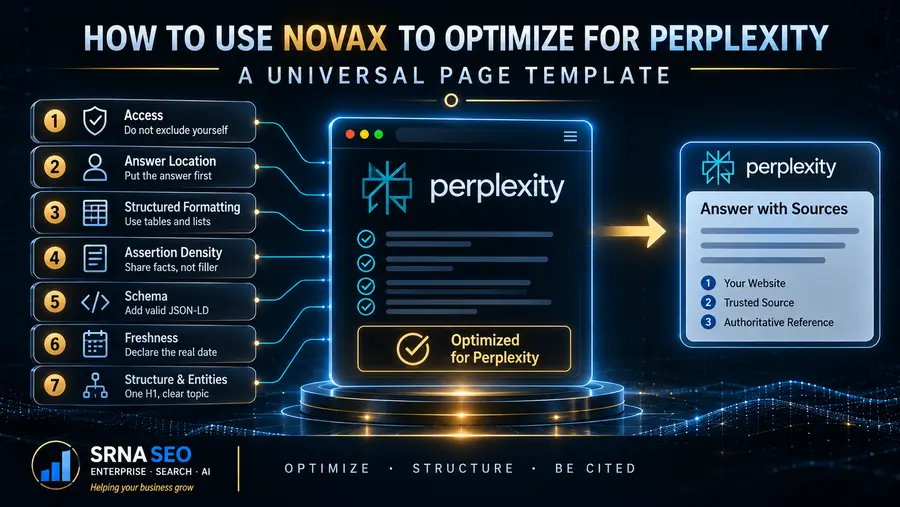
The Universal Perplexity Page Template
Seven blocks cover everything the Perplexity profile checks, and they apply to any page on any site. Work through them in order. The first is about not locking yourself out. The next three are about how the content itself is written and laid out, and the last three cover the markup, the dates and the structure around it.
1. Access: do not exclude yourself
- – Goal: Perplexity’s search crawler can reach the page, the page can be indexed, and the canonical URL points where you intend.
- – NovaX checks: whether PerplexityBot is blocked (the report says a block drops citation probability to zero), whether the page carries
noindexornofollow, and whether a canonical URL is set. A missing canonical may lead Perplexity to cite a duplicate instead of your intended URL. - – What Perplexity documents: its crawler documentation lists two agents. PerplexityBot is designed to surface and link websites in Perplexity search results, and Perplexity says it is not used to crawl content for AI foundation models. Perplexity-User supports actions a user starts, and because a user triggers the fetch, it generally ignores robots.txt rules. The settings are independent, and changes can take up to 24 hours to be reflected.
- – You check by hand: the robots.txt rules for both agents, and your firewall and CDN. Perplexity’s own guidance is to allow each bot by matching its user agent together with its published IP ranges, and to place that rule above any blocking rules. It also warns that Cloudflare’s Bot Fight Mode cannot be skipped with custom rules, so it may still challenge these bots. A page scanner cannot see any of this. For wider crawl and indexation problems, start with the Indexation and Crawl Diagnostic.
- – Done when: you can name the rule that governs each Perplexity agent on this site, the page carries no
noindexby accident, and the canonical matches the URL you want cited.
2. Answer location: put the answer first
- – Goal: the exact answer to the target query sits in the first two or three sentences, where a retriever looks first.
- – NovaX checks: the “first 30% rule”, meaning whether the answer appears in the top viewport or the first paragraphs. The report’s reasoning is that Perplexity extracts from the first retrievable content block, so answers buried under an introduction lose to pages that lead with the answer.
- – Fix: move the primary definition or answer into the opening paragraph and state it in plain terms. Then explain. Do the same under each H2, with the direct answer in the first sentence of the section. A bolded lead sentence does this job well.
- – A rule I apply: the first paragraph has to answer the query on its own, in a form someone could quote without the rest of the page. If you have to read paragraph three to understand paragraph one, the answer is not first.
- – Done when: you can copy the first paragraph into a chat window and it answers the question.
3. Structured formatting: tables and lists for the facts
- – Goal: comparisons, specifications and statistics live in tables and lists, not in prose a retriever has to interpret.
- – NovaX checks: at least three structured lists or one table. The report says even one well-built table can significantly lift the extraction score, and that prose paragraphs are often skipped because they need interpretation.
- – Fix: turn each comparison, each specification set and each stat-heavy passage into an HTML table or a bulleted list. Use real HTML tables with header cells, not images of tables and not layout built from divs. Keep each row about one thing.
- – A rule I apply: do not break reasoning into bullets. An argument chopped into fragments loses the “because” that made it an argument. Tables are for facts that share attributes. Prose is for reasons.
- – Done when: every set of facts that share attributes is in a table, and the page still reads as an argument.
4. Assertion density: facts, not filler
- – Goal: the page is made of definite, checkable statements.
- – NovaX checks: assertion density, the share of content that is declarative and concrete against marketing filler. The report’s own example contrasts a statement with a number in it with “committed to excellence”, and suggests at least one declarative fact per 50 words.
- – Fix: cut superlatives and brand-speak. Replace each with something verifiable: a number, a date, a named standard, a named product, a measured result. Remove paragraphs that exist only to introduce the next paragraph.
- – A rule I apply: remove filler, not caveats. A sentence that states the limits of a claim is a fact about the claim, and deleting it to raise a density score makes the page less true. The one-fact-per-50-words figure is NovaX’s heuristic, not a published threshold.
- – Done when: each paragraph contains something a reader could check, and no sentence would survive deletion only because it sounds good.
5. Schema: valid JSON-LD that matches the page
- – Goal: the page carries valid structured data that describes what is visibly on it.
- – NovaX checks: that Article, FAQ or HowTo schema is present. This is the heaviest weight in the profile, 35%, and the report calls JSON-LD the number one trust signal for Perplexity.
- – Fix: an Article block with a real author, a publisher,
datePublishedanddateModified. Add FAQPage markup only where the page carries a visible FAQ whose text it matches. Add HowTo markup only where the page is a real step-by-step procedure. Validate the JSON-LD, and keep every value in line with the visible text. - – A rule I apply: schema describes the page. It does not replace it. A page with perfect markup and an answer buried in paragraph six has solved the wrong problem. I also hold the 35% weight loosely, for the reasons in the evidence section below.
- – Done when: the markup validates, and every value in it can be found on the page.
6. Freshness: declare the real update date
- – Goal: Perplexity can see when the page was last materially changed.
- – NovaX checks: whether
dateModifiedis present in the JSON-LD, and the freshness score. This is the one engine-specific check that failed in the example report. NovaX raises it as a HIGH issue, on the reasoning that withoutdateModifiedPerplexity cannot confirm freshness and deprioritises the page in live retrieval. - – Fix: add
dateModifiedto every JSON-LD block on the page, matching the visible “Updated” date. If the page has not changed since it was published,dateModifiedequal todatePublishedis accurate, and it is better than leaving the field out. - – Rule: change the date only when the content changes. The projected +10 is a reason to declare the real date, not a reason to move it. A date that moves without an edit is a signal you do not want to teach an engine to distrust. Freshness also matters unevenly: recency probably counts most for news, prices and releases, and less for evergreen topics, and Perplexity publishes no window.
- – Done when: the schema date, the visible date and the actual last edit agree.
7. Structure and entities: one H1, and a topic that cannot be mistaken
- – Goal: the headings mark clear boundaries a retriever can cite, and the page names what it is about.
- – NovaX checks: structural integrity (a single H1 and a logical hierarchy, so topics can be extracted with confidence and citation boundaries detected), and an entity clarity score, with the Queries and Entities tabs behind it.
- – Fix: one H1, H2s for the main sections, H3s only inside them, with no skipped levels. Phrase headings so each says what its section answers. Check the rendered HTML as well as the editor, because themes and page builders sometimes add a second H1. Define each brand, tool and concept once, early, so it cannot be confused with something else of the same name. Then read the Queries tab and remove anything that is navigation or footer text rather than a real question.
- – Done when: the outline, read on its own, describes the page, and every extracted question is one a real reader would ask.
Ready to see how Perplexity sees you?
If you would like the access, schema, freshness and content gaps scoped across a whole site, that is the work I do in Enterprise Search Advisory, and you can talk to me here.
The schema skeleton for blocks 5 and 6
Adapt this, and do not paste it as is. Every value must match what is visible on the page. Include the FAQPage part only if the page has a visible FAQ with the same questions and answers.
{
  "@context": "https://schema.org",
  "@graph": [
    {
      "@type": "Article",
      "mainEntityOfPage": "https://example.com/your-page/",
      "headline": "Your page title",
      "datePublished": "2026-01-15",
      "dateModified": "2026-11-21",
      "author": {
        "@type": "Person",
        "name": "Author Name",
        "url": "https://example.com/author/author-name/"
      },
      "publisher": {
        "@type": "Organization",
        "name": "Your Organization",
        "url": "https://example.com/"
      }
    },
    {
      "@type": "FAQPage",
      "mainEntity": [
        {
          "@type": "Question",
          "name": "A question that is visible on the page?",
          "acceptedAnswer": {
            "@type": "Answer",
            "text": "The same answer text that is visible on the page."
          }
        }
      ]
    }
  ]
}
A Worked Example: One Page, One Report
A page can score 89 out of 100 with a strong citation probability, and still have one concrete fix that outweighs everything else on the list. Here is a real NovaX Perplexity report for one page, my own page on SEO revenue accountability. The specific numbers will differ on your pages. The reading order will not.
The headline: Engine Score 89 (“Strong”), Citation Probability 68% (“strong citation eligibility”), PerplexityBot allowed, and five of six engine-specific checks passing. The one failure is dateModified in the JSON-LD, which NovaX raises as the only issue, rated HIGH. The five core signals read structural integrity 100, entity clarity 100, schema and metadata 100, data extractability 80 and freshness and decay 72. All three research-backed signals (answer location, tabular formatting and assertion density) show as present.
| What the report shows | What I make of it | Action | Priority |
|---|---|---|---|
| Last Inspector run was 39 days ago | Every number below describes an older version of the page | Re-inspect first | 1 |
Issue: no dateModified in JSON-LD, projected +10 | The single concrete failure, and the largest projected gain (block 6) | Add it, matching the real last edit | 2 |
| Freshness 72, the lowest core signal | Consistent with the missing date, and likely to rise once it is declared | Re-inspect after the fix, then update the content if it has genuinely aged | 3 |
| Extractability 80 with all three research signals present | Presence is a pass or fail. The score is graded, so there is headroom in how much is structured (blocks 3 and 4) | Check the Recommendations tab, then add a table or list where facts sit in prose | 4 |
| Structural integrity, entity clarity and schema all at 100 | Blocks 5 and 7 are satisfied | Protect them: do not lose them in a redesign or a template change | 5 |
| Queries and Entities tabs | A passing checklist does not guarantee that the extracted questions and entities are clean | Open both and read the lists | 6 |
Three things in that table are worth saying out loud.
One failed check can cost more than several small gaps. The projected +10 for dateModified is larger than anything the report offers for the other signals. A page can be nearly perfect on layout and still be marked down on one field that takes five minutes to add. Fix the concrete, cheap failure first.
The fix is only worth the date being true. Declaring a real dateModified is honest. Setting it to today to collect the projected points is not, and the freshness signal would then describe a page that did not change. If the content has not been touched, the accurate value is the original publication date. If it has aged, the right fix is an update, then the date.
A strong probability still has a gap. The 68% sits below the 89. In this report the named cause is the missing date. After that is fixed, any remaining gap comes from what a page cannot control, such as which other pages compete for the same few source slots. I explained in the optimize article that Perplexity shows fewer sources per answer than ChatGPT, on figures I could not verify at the original source, which makes each slot more contested.
The result of working that list is a re-inspected page with a higher projected score. It is not a guarantee of citations, which is the subject of the next section.
What NovaX Measures vs What Perplexity Documents
A NovaX score is a model of what tends to go with eligibility. It is not Perplexity’s own weighting, and nobody outside Perplexity has that. I built NovaX, so you should read my claims for it with that in mind. In the optimize article I noted that Perplexity publishes no ranking formula, and that applies to NovaX as much as to any other tracker.
So the weights in the report, such as the 35% on schema, are NovaX’s modelling choices. Here is how each part of the template stands against what Perplexity itself says, as I read it from the sources I cited in the optimize article.
| Template block | Perplexity’s position or the outside evidence | NovaX’s treatment | My read |
|---|---|---|---|
| 1. PerplexityBot allowed | Documented: it surfaces and links sites in Perplexity search results | Pass or fail check | Do first. The strongest evidence of any block |
| 1. Perplexity-User | Documented: user-initiated, generally ignores robots.txt | Not checked | Control it at the firewall, not in robots.txt |
1. noindex and canonical | Not documented in the pages I read | Pass or fail checks | Standard hygiene. The consequence is NovaX’s claim |
| 2. Answer first | Not documented. Vendor practice | Research-backed signal | Cheap. Do it |
| 3. Tables and lists | Not documented. Vendor practice | 3+ lists or 1+ table | Cheap. Good writing for a reader in a hurry as well |
| 4. Assertion density | Not documented | One fact per 50 words | A useful editing test. The number is NovaX’s |
| 5. Article, FAQ and HowTo schema | Not documented. One vendor reports a 3.2x citation correlation for FAQ schema, which I rate weak. The ChatGPT study I cited found the opposite | Weighted 35%, the highest | Valid Article markup is hygiene. Treat the weight as a hypothesis |
6. dateModified and freshness | Not documented. Recency plausibly matters most for time-sensitive topics | 20% weight, +10 projected in the example | Cheap and honest if the date is real |
| 7. Heading structure and entities | Not documented | 17% weight, plus entity clarity | Cheap. Do it |
What a score can and cannot do follows from that table. It can show you whether a page is complete against a defined checklist, order your fixes by projected payoff, catch regressions after a template change, and compare pages on the same site. It cannot prove that a fix caused a citation, show which Perplexity mode used the page, or see your robots.txt, your firewall or your CDN.
The table also shows an uncomfortable fact. The heaviest weight in the profile, 35% on schema, sits on the least documented area. I do not know of anything from Perplexity that says Article, FAQ or HowTo markup raises a page’s chance of being cited. The profile may be right, and the markup is cheap, so I do it. But I would not spend a quarter on schema before the answer is at the top of the page and the access rules are checked.
The Fix-and-Verify Loop
Run the loop on one page first, then on the pages that matter most, and keep each round small enough to attribute. Changing seven things at once tells you nothing about which one worked.
- 1. Inspect. Run the page through NovaX and open the Perplexity report. Note the Engine Score, the Citation Probability and the date of the inspection.
- 2. Check access by hand. Confirm the robots.txt rules for PerplexityBot, look at the firewall and CDN rules for both Perplexity agents, and confirm there is no stray
noindex, because the report cannot see all of them. - 3. Simulate. Use the Simulator to see which fixes carry the highest projected impact, and tick the ones you plan to make.
- 4. Fix in template order. Work through blocks 1 to 7, cheapest and most concrete first. Fix site-wide problems, such as a second H1 from the theme, a missing
dateModifiedin the schema plugin, or navigation read as questions, in the template and not page by page. - 5. Allow time. Perplexity says a robots.txt change can take up to 24 hours to be reflected. Do not re-inspect the same hour.
- 6. Re-inspect. Run the page again and compare. Did the blocks you touched improve, and did anything else regress?
- 7. Measure over time. A score changing is not the same as being cited more, and Perplexity can return different sources for the same prompt, so one check proves little. For that, track presence over repeated runs with the method in How to Measure Your Presence in Perplexity, and see AI Search Visibility Share of Voice for the wider picture.
Two supporting reads help at the writing stage: How to Write a Blog Post for AI SEO and Citations and AI Content Structure for Enterprise Visibility. For the schema side in more depth, see Schema Markup for AI Search: What Actually Matters?
Where to Go From Here?
Start with the AI Visibility Inspector on one page you care about, and work the seven blocks in order. When you need Perplexity tracked across your pages and against named competitors over time, NovaX covers it. And if you want the access, schema, freshness and content gaps scoped for your organization, contact me.
What This Is NOT
This is not a promise that a higher score earns more citations. It is not a replacement for the access checks, which no page scanner can do for you. It is not a claim that Perplexity uses NovaX’s weights, because it does not publish its own. And it is not a case for adding markup in place of putting the answer first, since answer location is the block a reader can verify by looking at the page.
It is a way to inspect one page against a defined checklist, fix the cheap and concrete gaps first, and confirm afterwards that the page actually changed.
FAQ
It is the engine profile that scores a page on speed and fact density: whether the answer is easy to find, easy to lift and stated as fact. It scores page-level signals. It does not tell you which Perplexity mode cited you.
The Engine Score shows how completely a page’s signals match the Perplexity profile. The Citation Probability is a more cautious eligibility estimate. They can differ, as an 89 score beside a 68% probability shows, and the gap is a reason to read the detail.
Per Perplexity, PerplexityBot is the agent that surfaces and links sites in its search results, and it is not used to crawl content for AI foundation models. Allow it if you want to be eligible. Perplexity-User is separate, acts on a user’s request and generally ignores robots.txt, so manage it at the firewall.
The profile reasons that real-time retrieval needs a date to confirm freshness, so a page without one is deprioritised. Perplexity does not document that, so I treat it as a plausible, cheap fix. Add the real date, and only change it when the content changes.
NovaX weights them heavily, but I know of no Perplexity documentation that says so. One vendor reports a correlation for FAQ schema that I rate weak, and a ChatGPT study I cited elsewhere found the opposite. Write a visible FAQ for readers, mark it up if it is accurate, and do not sell it as a guaranteed tactic.
No. The profile rewards answers that appear early and facts that are easy to lift. A long page can pass every check if the first paragraph answers the query and the facts sit in tables. Cut filler, not substance.
The report passes a page at three or more structured lists or at least one table. That threshold is NovaX’s. Use a table wherever facts share attributes, and a list where items are parallel.
After any material change, and before acting on a report that is old. In the worked example the last inspection was 39 days earlier, so the first step was to run it again.
No. You can promise a baseline, a fixed set of changes and repeated measurement.
This article was researched and drafted with the assistance of AI tools and reviewed and edited by author prior to publication.
