

In This Article
Knowing which Anthropic crawler does what is half the job. The other half is knowing what to fix on one specific page. This article is the page-level workflow: a seven-block template you can run against any URL, and how NovaX shows you which block is failing.
In How to Optimize Your Website for Claude I covered what Anthropic documents: the three ways Claude can know about a site, which crawler controls which path, and what is guesswork. I will not repeat that here. This article asks a narrower question. Given a single page, what do you look at, in what order, and how do you know afterwards whether anything changed?
I use NovaX for that. It scores each page against engine-specific signals, one engine at a time. For Claude, it models one particular idea: that the engine behaves like a logic, nuance and neutrality filter, one that prizes a single clear topic, an explicit author and analytical prose. That model is useful, and it is also a model, not a view inside Anthropic. I keep the two apart throughout, and the section on evidence levels says exactly where the line sits. Of the engine profiles in this series, this is the one where that distinction matters most, because Anthropic documents the least about page-level selection.
What is in This Series
This article is part of the cluster How to Measure Your Presence in AI Search Engines. The hub also contains AI Search Visibility Share of Voice, and a pair of articles for each engine:
- – ChatGPT: Official guide, How to measure and How to optimize with NovaX
- – Perplexity: Official guide, How to measure and How to optimize with NovaX
- – Claude: Official guide, How to measure and How to optimize with NovaX
- – Gemini: Official guide, How to measure and How to optimize with NovaX
- – Copilot: Official guide and How to measure
- – Grok: Official guide and How to measure
- 1. The official guide articles say what the engine’s owner documents.
- 2. The measure articles say how to track presence over time.
- 3. The How to optimize with NovaX sits between them: it is the hands-on step where you inspect a page and decide what to change.
What the Claude Engine Is?
Claude is the logic, nuance and neutrality engine: it asks whether a page has one clear topic, whether it has a verifiable author, and whether it argues in a way that holds up. Those are the three questions the engine profile is built around, and every signal in the report maps to one of them.
- – Is the topic unambiguous? Does the page have a single H1 and a heading hierarchy that nests cleanly, so there is one primary topic and every section belongs to it? This carries the largest weight in the profile, 45%.
- – Is the source verifiable? Is there an explicit author, expressed as Person schema alongside Article schema, with named entities that schema backs up? Entity clarity carries 30%.
- – Does the argument hold? Is the prose analytical and neutral, and are claims introduced, supported and concluded? Extractability, meaning content depth and paragraph structure, carries the remaining 25%.
None of the three is something Anthropic documents as a selection criterion. Anthropic publishes crawler controls and web search tool documentation, and, as I noted in the optimize article, its search documentation names no search provider and describes no ranking. So the three questions are NovaX’s way of turning “structured, analytical and objective” into things a crawler can check on a page. The profile’s own description says Claude is “uniquely sensitive to ambiguous topic signals”. I read that as a hypothesis from the profile’s builder, which is me, and not as a published fact.
Two points of scope matter before you read any score. First, “Claude” covers three paths: what the model learned in training, what it finds through web search, and what it fetches when a user supplies a URL. The NovaX profile scores page-level signals that are relevant to the search and fetch paths. It cannot see the memory path, and it does not tell you which path produced an answer. Second, the search backend depends on the deployment. Anthropic’s documentation does not cover the consumer app in this respect, so there is no single “Claude index” for a page score to correspond to. That is the main reason I hold the weights in this report loosely.
How to Read the NovaX Claude Report
Read two numbers first, then the signals underneath them, and never act on the headline alone. A Claude report opens with an Engine Score out of 100 and a Citation Probability as a percentage. They answer different questions, and they can disagree.
- – Engine Score: how completely the page’s signals match what the Claude profile looks for. The report adds a score trend, and a comparison with your workspace average once you have inspected more pages.
- – Citation Probability: a more cautious eligibility estimate. In the report I am using as the example, a page scored 75 out of 100 and 43% citation probability, and NovaX labelled that “moderate eligibility”, with a note to address the critical issues to push above 60%.
Those two are not the same. Here the gap is wider than in the other reports in this series, and the report gives a named reason for it: three critical issues, all about schema and authorship. The worked example below reads those issues carefully, because on this particular page they are not what they first appear to be.
The engine weights its score in three parts:
| Component | Weight | What it covers for Claude |
|---|---|---|
| Structural integrity | 45% | A single unambiguous H1 as the primary topic anchor, and a clean heading hierarchy |
| Entity clarity | 30% | Schema-backed named entities, with Person and author schema as core signals |
| Extractability | 25% | Content depth and paragraph structure for clean reasoning and citation extraction |
Structural integrity at 45% is higher than in the Gemini (15%), ChatGPT (30%) and Perplexity (17%) profiles. Schema and metadata appear as a fifth core signal, and so does freshness, but neither has a listed weight here. Schema reaches the score through entity clarity, and I read freshness as supporting context.
The tabs then split the page into parts you can act on:
| Tab | What it tells you | What you do with it |
|---|---|---|
| Overview | Score, trend, citation probability, top actions, issues, engine-specific checks | Decide where to start |
| Signals | The five core signals scored individually | Find the weakest block of the template |
| Simulator | Projected score impact of each fix | Order fixes by payoff before you touch the page |
| Queries | The questions found on the page and how eligible each is | Spot weak or noisy question headings |
| Entities | Entities detected, their type, schema status and clarity | Decide which entities need markup or a clearer definition |
| Recommendations | Specific issues raised by the Inspector | Fix the cheap, concrete ones, and read them with care |
| Freshness | Freshness score and sensitivity for the engine | Decide whether the page is due an honest update |
One caution on the Recommendations tab. It comes from the Inspector, which looks at the page across engines, and not only from the Claude profile. In the example report, one recommendation says authorship signals matter for Perplexity and Gemini, and another says Gemini scores visual context separately. Read those as general page advice, not as statements about Claude.
The Simulator is the part I use most. You tick the fixes you plan to make and it projects the score change. In the example, adding Person schema was projected at +12 and adding Article schema at +9. Taken at face value that is 96, but projections do not always add, and, as the next sections show, on this page I would not make both changes.
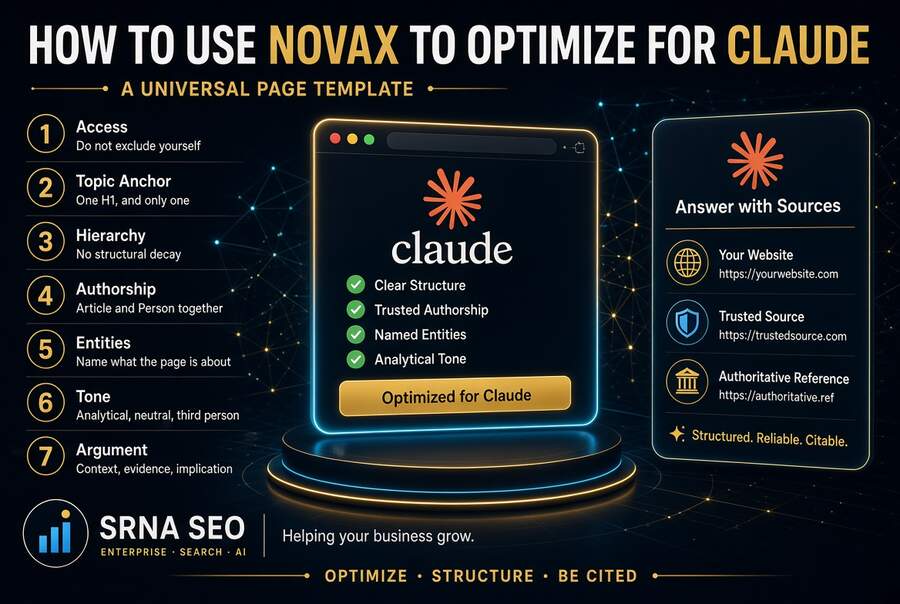
The Universal Claude Page Template
Seven blocks cover everything the Claude profile checks, and they apply to any content page on any site. Work through them in order. The first is about not locking yourself out. The next two are the structural blocks that carry the heaviest weight. The remaining four cover authorship, entities, tone and argument.
Access: do not exclude yourself
- – Goal: Anthropic’s crawlers can reach the page, and the page carries no accidental exclusion.
- – NovaX checks: whether ClaudeBot is blocked, and whether a robots
noindexis present. The report says blocking ClaudeBot removes the page from Claude’s index entirely, and thatnoindexremoves it from Claude’s retrieval and training corpus. - – What Anthropic documents: its robots.txt controls page names three bots. ClaudeBot collects web content that may be used to train its models, and blocking it signals that future materials should be excluded from training. Claude-User accesses sites when a user’s question needs web content, and blocking it may reduce visibility for user-directed search. Claude-SearchBot crawls to improve the quality and relevance of search responses, and blocking it may reduce visibility in user search results. That page does not mention
noindex. So I read the NovaX ClaudeBot check as a sign that someone has or has not blocked Anthropic’s crawlers in general, and I confirm Claude-SearchBot and Claude-User separately. - – You check by hand: the robots.txt rules for all three bots, and the page’s own robots meta tag and response headers. Anthropic says its bots honor robots.txt, supports
Crawl-delayas a non-standard extension, and warns that IP blocking may not work reliably because it can stop the bot reading robots.txt. It also says that from October 30, 2026 it recognizes a machine-readable “no AI training” signal based on an IETF draft, and that a robots.txt rule naming ClaudeBot takes priority for a given path. I have not tested that behaviour. Whether to allow training is an intellectual property decision, as I explain in Everything You Need to Know About AI Intellectual Property. For wider crawl and indexation problems, start with the Indexation and Crawl Diagnostic. - – Done when: you can name the rule that governs each Anthropic agent on this site, and the page’s robots meta and headers say what you intend.
Topic anchor: one H1, and only one
- – Goal: there is one primary topic, and it is stated in a single H1.
- – NovaX checks: that the page has exactly one H1. The report calls multiple H1s Claude’s strongest negative signal, because the engine then cannot determine the primary topic.
- – Fix: one H1 that names the page’s subject in plain words. Check the rendered HTML as well as the editor, because themes and page builders sometimes add a second H1 through a logo, a hero block or a widget, and the editor will not show it.
- – A rule I apply: the H1 should describe what the page is about, not what the page sells. A promotional H1 fails the tone check in block 6 before the text begins.
- – Done when: a view of the source shows one H1, and it matches the topic of the title tag.
Hierarchy: no structural decay
- – Goal: the headings form a nested outline in which every section belongs to its parent.
- – NovaX checks: that H1, H2 and H3 follow a logical flow, with no skipped levels and no H2 on an unrelated topic. The profile’s phrase is “structural decay”, and its reasoning is that long-context processing notices headings that skip, repeat or contradict the argument.
- – Fix: write the outline before you write the page. Every H2 is a subtopic of the H1. Every H3 is a subtopic of its H2. Name each heading for what the section answers. Run the page’s outline through a heading checker and read it on its own.
- – A rule I apply: do not use heading tags for styling. A bold line that is not a section should not be an H3.
- – Done when: the outline, read alone, tells the argument of the page.
Authorship: Article and Person together
- – Goal: the page names a real author, in markup and in the visible text.
- – NovaX checks: Article schema (or BlogPosting, FAQPage or HowTo), and Person schema. The report calls Article plus Person the minimum for citation eligibility, and says Claude weighs authorship most heavily of all engines.
- – Fix: an Article with a real author, a
jobTitle, a link to an author page and, where one exists, asameAslink to a professional profile. Add the publisher as an Organization. Keep the visible byline and the markup describing the same person. - – Which pages this applies to: pages that are articles. A category archive or a listing page is not an article, and marking it up as one would describe something the page is not. For those pages, see the worked example.
- – A rule I apply: do not invent a credential to fill a field. A missing
sameAslink is better than a false one. - – Done when: the schema and the visible byline describe the same people, and each article page carries both.
Entities: name what the page is about
- – Goal: the main topics and the people and organizations around them are named plainly and consistently.
- – NovaX checks: a clarity score for each entity, with schema backing counted in. The Entities tab lists what it detected, with type and schema status.
- – Fix: define each brand, tool and concept once, early, so it cannot be confused with something else of the same name. Use the same name for it everywhere on the page. For entities that exist outside your site, link to a reliable reference where one exists.
- – A rule I apply: do not forge
sameAslinks for terms you coined. A framework you named has no Wikipedia page. Define it in the text and expect lower clarity for it. That is an honest reading. - – Done when: each entity has one name, one definition and, where it exists, one outside reference.
Tone: analytical, neutral, third person
- – Goal: the prose reads as objective analysis and not as a pitch.
- – NovaX checks: the “academic and analytical tone” signal, meaning the absence of promotional language, exclamation marks and aggressive sales framing. The report says this matters more for Claude than for any other engine, and that promotional content is flagged as low authority regardless of schema or structure.
- – Fix: audit each paragraph for superlatives, exclamation marks and first-person sales language. Replace each with a third-person statement backed by a number, a date or a source.
- – A rule I apply: neutrality does not mean hiding who you are. A disclosure such as “I built NovaX” is part of an objective account, because it tells the reader how to weigh the claim. Remove the pitch, keep the disclosure.
- – Done when: a reader could not tell from the prose what the page’s author hopes to sell.
Argument: context, evidence, implication
- – Goal: every substantial claim is introduced, supported and concluded.
- – NovaX checks: the “premise to conclusion flow” signal, and, through extractability, content depth and paragraph structure. The report’s example is a claim such as “our system is 40% more efficient” with no context or support, which it treats as an unsubstantiated assertion.
- – Fix: for each major claim, add one sentence of context before it and one sentence of implication after it. The profile’s formula is context, then evidence, then implication, and it calls this the highest-value prose fix for Claude. Keep the central claim short and self-contained. Anthropic’s search documentation describes citations that carry a short excerpt of the cited text, and my reading is that a claim which survives being quoted alone is the safer form. That is inference.
- – A rule I apply: do not turn every sentence into a claim. Evidence-free assertions are the problem, not plain statements of fact.
- – Done when: for each claim you can point to the evidence on the page and the sentence that says what follows.
Ready to see how Claude sees you?
If you would like the access, structure, authorship and content gaps scoped across a whole site, that is the work I do in Enterprise Search Advisory, and you can talk to me here.
The schema skeletons for block 4
Adapt these, and do not paste them as they are. Every value must match what is visible on the page. The first is for an article. The second is for a listing page such as a category archive, where an Article would misdescribe the page.
{
  "@context": "https://schema.org",
  "@type": "Article",
  "mainEntityOfPage": "https://example.com/your-article/",
  "headline": "Your article title",
  "datePublished": "2026-01-15",
  "dateModified": "2026-11-21",
  "author": {
    "@type": "Person",
    "name": "Author Name",
    "jobTitle": "Their real job title",
    "url": "https://example.com/author/author-name/",
    "sameAs": ["https://www.linkedin.com/in/author-profile/"]
  },
  "publisher": {
    "@type": "Organization",
    "name": "Your Organization",
    "url": "https://example.com/"
  }
}
{
  "@context": "https://schema.org",
  "@type": "CollectionPage",
  "url": "https://example.com/category/topic/",
  "name": "Category: Topic",
  "isPartOf": {
    "@type": "WebSite",
    "name": "Your Organization",
    "url": "https://example.com/"
  },
  "mainEntity": {
    "@type": "ItemList",
    "itemListElement": [
      {
        "@type": "ListItem",
        "position": 1,
        "url": "https://example.com/first-article/"
      }
    ]
  }
}
A Worked Example: One Page, One Report
A page can score 75 out of 100 with three critical issues, and the first job is to ask whether the report is describing the right kind of page. Here is a real NovaX Claude report for one page. It is not an article. It is the category archive for Diagnostics and Recovery on this site. I chose it because it shows how a profile built for articles reads a page that is not one. The specific numbers will differ on your pages. The reading order will not.
The headline: Engine Score 75 (“Good”), Citation Probability 43% (“moderate eligibility”), ClaudeBot allowed, and three of six engine-specific checks passing. The five core signals read data extractability 85, freshness and decay 81, structural integrity 75, entity clarity 65 and schema and metadata 50. Three critical issues are listed: no content schema, missing Person schema, and an incomplete authorship chain. The three research-backed signals (analytical tone, logical hierarchy and premise-to-conclusion flow) all show as present.
| What the report shows | What I make of it | Action | Priority |
|---|---|---|---|
| Last Inspector run was 74 days ago | Every number below describes an older version of the page | Re-inspect first | 1 |
| Page type: a category archive, with three critical issues | The issues ask for article-type schema and an author, which an archive does not have | Decide the page type first. Do not add Article to the archive | 2 |
Check “No robots noindex” shows as failed, though the live page’s robots meta currently reads index,follow | The check and the page disagree, so the report is stale, mislabelled or reading something else | View the source and the response headers, then re-inspect | 3 |
| Entity clarity 65, schema 50, the two lowest signals | Both depend on schema backing. On an archive, the real fix sits one level down | Run the same inspection on the articles the archive lists | 4 |
| Structural integrity 75 at a 45% weight | An archive whose only heading is the H1 has little hierarchy to score | Add short section headings if the page has real sections. Do not invent them | 5 |
| Analytical tone, logical hierarchy and premise-to-conclusion flow all present | Blocks 3, 6 and 7 are satisfied | Protect them in any template change | 6 |
| Recommendations: Article and Person schema, 3 images without alt text, a quarterly refresh cadence | Generic Inspector advice, partly written for other engines | Do the alt text. Take the refresh cadence as written, and move dateModified only on a real edit | 7 |
Four things in that table are worth saying out loud.
Check the page type before you read the issues list. The three critical issues reduce to two missing things, article schema and author schema, and the third issue restates them. Both belong on article pages. A category archive lists articles. Marking it up as an Article would describe a page that is not an article, and the markup has to match the visible page. The honest options are listing-page markup such as CollectionPage, which the report may not count toward its checks, or accepting that the schema checks do not fit this page type. The projected +21 for adding both is a reason to ask whether the archive should be the audited page at all.
A listing page is a weak citation target by design. A category archive routes readers and crawlers to articles. It is rarely the single page that answers a question well. So a 43% probability on an archive is not necessarily a problem to solve. The articles inside it are the pages I would want cited, and those are the pages to inspect. This is my judgment, not something the report says.
A failed noindex check on an indexable page is a reason to inspect. When I looked at the live archive, its robots meta tag read index,follow and its canonical matched its own address. The report is 74 days old. Either something changed, the check treats a missing directive as a failure, or something outside the HTML, such as a response header, is involved. I cannot tell which from the report, and the issues list does not mention it. Look at the source and the headers before acting.
Do not chase the last points with a forced heading structure. The profile rewards hierarchy, and a listing page has little. Adding headings that exist only to be counted would produce the structural decay the profile penalises.
The result of working that list is a re-inspected page, a clearer decision about which pages deserve this audit, and a short fix list for the pages that do. It is not a guarantee of citations, which is the subject of the next section.
What NovaX Measures vs What Anthropic Documents
A NovaX score is a model of what tends to go with eligibility. It is not Anthropic’s own weighting, and nobody outside Anthropic has that. I built NovaX, so you should read my claims for it with that in mind. I do not know of any third party with access to how Claude selects sources, and that applies to NovaX as much as to any other tracker.
So the weights in the report, such as the 45% on structure, are NovaX’s modelling choices. Here is how each part of the template stands against what Anthropic itself says, as I read it from the sources I cited in the optimize article.
| Template block | Anthropic’s position or the outside evidence | NovaX’s treatment | My read |
|---|---|---|---|
| 1. Claude-SearchBot and Claude-User allowed | Documented: they relate to search and user-directed retrieval | Not checked directly | Do first. The strongest evidence of any block. Verify by hand |
| 1. ClaudeBot decision | Documented: relates to training | Pass or fail engine check | An intellectual property call as much as an SEO call |
1. noindex | Not mentioned on the pages I read | Pass or fail check | Standard hygiene. The stated consequence is NovaX’s claim |
| 2. Single H1 | Not documented | Weighted inside the 45% | Cheap. Do it for readers as well |
| 3. Heading hierarchy | Not documented | Weighted inside the 45% | Cheap. Do it |
| 4. Article and Person schema | Not documented. NovaX says Claude weighs authorship most heavily of all engines | Core entity signal, 30% | Sound identity hygiene. Treat the ranking of engines as a hypothesis |
| 5. Entity clarity | Not documented. Consistent entity descriptions are my inference | Weighted 30% | Plausible and cheap |
| 6. Analytical tone | Not documented as a selection factor | Research-backed signal | Good writing regardless of the engine. The effect on citation is unproven |
| 7. Context, evidence, implication | Not documented. Anthropic documents short cited excerpts, and my link from that to claim length is inference | Research-backed signal | Cheap and good for readers. Do it |
What a score can and cannot do follows from that table. It can show you whether a page is complete against a defined checklist, order your fixes by projected payoff, catch regressions after a template change, and compare pages of the same type on the same site. It cannot prove that a fix caused a citation, show which of Claude’s paths used the page, or see your robots.txt, your headers or your firewall.
The table also shows how thin the documented side is. Of the seven blocks, only the crawler controls in block 1 have an Anthropic source. The other six are practice, vendor reasoning or my own inference. They are inexpensive and, for the most part, good writing and good markup anyway. But I would not present any of them to an executive as a proven lever for Claude.
The Fix-and-Verify Loop
Run the loop on one page first, then on the pages that matter most, and keep each round small enough to attribute. Changing seven things at once tells you nothing about which one worked.
- 1. Inspect. Run the page through NovaX and open the Claude report. Note the Engine Score, the Citation Probability, the page type and the date of the inspection.
- 2. Check access by hand. Confirm the robots.txt rules for ClaudeBot, Claude-SearchBot and Claude-User, view the page’s robots meta and response headers, and look at firewall rules, because the report cannot see all of them.
- 3. Simulate. Use the Simulator to see which fixes carry the highest projected impact, and ask for each one whether it fits the page type.
- 4. Fix in template order. Work through blocks 1 to 7, cheapest and most concrete first. Fix site-wide problems, such as a second H1 from the theme or schema that is missing from every article, in the template and not page by page.
- 5. Allow time. Anthropic’s bots have to recrawl the page, and no document gives a window. Do not re-inspect the same hour.
- 6. Re-inspect. Run the page again and compare. Did the blocks you touched improve, and did anything else regress?
- 7. Measure over time. A score changing is not the same as being cited more. Claude’s answers can come from memory or from search, and one check proves little. For that, track presence over repeated runs, with search on and off, using the method in How to Measure Your Presence in Claude, and see AI Search Visibility Share of Voice for the wider picture.
Two supporting reads help at the writing stage: How to Write a Blog Post for AI SEO and Citations and AI Content Structure for Enterprise Visibility. For the schema side in more depth, see Schema Markup for AI Search: What Actually Matters?
Where to Go From Here?
Start with the AI Visibility Inspector on one article you care about, and work the seven blocks in order. When you need Claude tracked across your pages and against named competitors over time, NovaX covers it. And if you want the access, structure, authorship and content gaps scoped for your organization, contact me.
What This Is NOT
This is not a promise that a higher score earns more citations. It is not a replacement for the access checks, which no page scanner can do for you. It is not a claim that Anthropic uses NovaX’s weights, because it does not publish its own. And it is not a case for adding markup to every page, since a listing page described as an article is a less accurate page, not a more visible one.
It is a way to inspect one page against a defined checklist, fix the cheap and concrete gaps first, and confirm afterwards that the page actually changed.
FAQ
It is the engine profile that scores a page on logic, nuance and neutrality: whether it has one clear topic, a verifiable author and an analytical argument. It scores page-level signals. It does not tell you which of Claude’s paths used the page.
The Engine Score shows how completely a page’s signals match the Claude profile. The Citation Probability is a more cautious eligibility estimate. They can differ, as a 75 score beside a 43% probability shows, and the gap is a reason to read the detail.
NovaX checks ClaudeBot, but Anthropic documents it differently. Per Anthropic, ClaudeBot relates to training, Claude-SearchBot to search quality and Claude-User to user-directed retrieval. Each has its own robots.txt rule. Check all three yourself, and treat the training decision as an intellectual property call.
On article pages, I add both, because they make authorship explicit and cost little. Anthropic does not document either as a selection factor. On listing pages such as category archives, an Article would misdescribe the page, so use listing-page markup or accept that the schema checks do not fit.
Because the profile expects article-type markup and an author, and an archive has neither. The three issues in the example reduce to two missing items. The useful question is whether the archive should be the page you audit.
It is cheap, and it is good structure for readers. NovaX gives structure its largest weight for Claude and calls multiple H1s the strongest negative signal. Anthropic does not document that. Fix a duplicate H1 because it is a defect, not because a score demands it.
The profile says it does and calls it the strongest tone effect of any engine. Anthropic does not document tone as a selection factor. Neutral, evidence-backed prose is better writing in any case, so the advice costs nothing to follow.
After any material change, and before acting on a report that is old. In the worked example the last inspection was 74 days earlier, and the live page no longer matched one of the checks, so the first step was to run it again.
No. You can promise a baseline, a fixed set of changes and repeated measurement.
This article was researched and drafted with the assistance of AI tools and reviewed and edited by author prior to publication.
