
In This Article
Your security team checks whether someone can break in, your SEO team begs AI systems to cite you, and nobody owns the question of what an AI can assemble about you from both. That gap is exactly what a knowledge exposure audit closes. The most important point of this whole article is simple: public is not the same as vulnerable, but a pile of harmless public facts can add up to something you would never publish on purpose.
Knowledge exposure is the total set of facts about your organization that an outside AI system can retrieve or reconstruct from your public footprint, including facts you never intended to put side by side. A knowledge exposure audit is the structured review of that footprint: what is served to an anonymous visitor, what an AI could infer from it, and whether each piece has a legitimate reason to be there.
This guide is the practical follow-up to my earlier piece on the question your security audit never asks. That one explained the problem. This one tells you what to open, what to close, and how to build the structure underneath.
What knowledge exposure is (and what it is NOT)
Let me clear the ground first, because this topic gets mixed up with three others.
It is not a penetration test. Nobody breaks in, nobody guesses a password, nobody touches a login. The audit only looks at what an anonymous visitor can already see.
It is not shadow AI monitoring either. Shadow AI is about employees pasting contracts into chat tools. Real problem, different team, different controls. If you want the internal side, the security vendors cover it well (the NHI Mgmt Group has a decent overview of how prompts, retrieval and outputs create their own exposure layer). Knowledge exposure is the outside-in view.
And it is not an attempt to make your organization invisible to AI. If that is what you want, you are reading the wrong website. Being found is the business. Bitdefender made a similar point in a recent small business piece: you cannot remove everything, and you should not try, the real question is whether each detail needs to be public.
So what is left? A very specific question. If an AI agent crawled everything public on your domain today, what confidential, proprietary or strategically sensitive knowledge could it put together?
Why your security audit does not see it
Standard security tooling is built around one question: can an attacker get in? It looks for CVEs, open ports, misconfigured servers. All useful. None of it asks whether the content you serve on purpose, to everyone, gives too much away.
| Traditional security | Knowledge exposure audit |
|---|---|
| Prevents unauthorized access | Audits authorized, public content |
| Monitors CVEs, firewalls, network state | Evaluates what an AI can reconstruct from it |
| Asks: can someone break in? | Asks: what does the public footprint already give away? |
The threat model is changing too. MITRE ATT&CK now lists a technique called Query Public AI Services (T1682), and the commentary around it makes the uncomfortable point that an adversary can ask public AI systems about your company from outside your network. You get no telemetry. No alert. Nobody emails to say “ChatGPT told me something odd about you.”
An AI crawler does not need to breach anything. It only needs what you already serve.
I will be honest, I did not take this seriously enough for years. In SEO we spend our whole career pushing more content, more pages, more signals into the open Internet. The idea that some of it should go the other way felt like someone else’s job. It is not. It is ours, because we control the publishing layer.
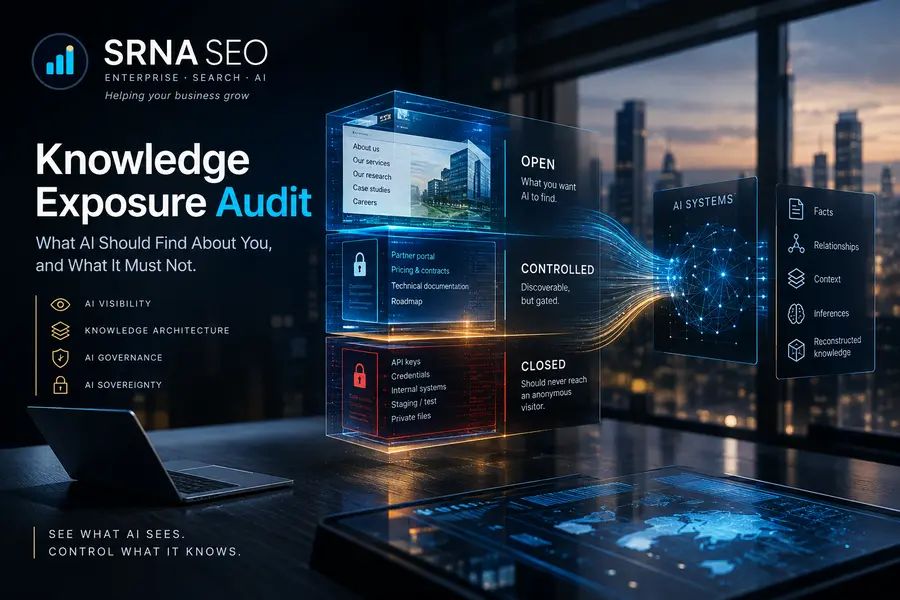
The three-zone model: open, controlled, closed
Here is the model I use. Three zones, one decision per piece of knowledge. I built it from how the audit classifies findings, so the two fit together.
Zone 1: Open (easily retrievable by public AI)
This is what you want AI systems to find, understand and repeat correctly. If AI gets this wrong, you lose business. If AI cannot find it, you lose more.
- Who you are: legal name, what you do, where you operate, leadership roles that are already public
- What you sell: products, services, categories, supported use cases
- Your positions: methodology summaries, published research, official statements
- Proof points you are comfortable being quoted on: awards, certifications, public case studies
- Corrections: the canonical answers to questions where AI currently gets you wrong
Open does not mean uncontrolled. Open knowledge should be explicit, consistent and easy to cite. That is the job of AI Visibility Inspector (my diagnostic tool for how AI systems read a site) and NovaX (my AI visibility intelligence platform), and it is also where entity work lives, more on that below.
Zone 2: Controlled (discoverable, but gated)
Some knowledge has real commercial value to the right reader and real cost if it reaches everyone. The pattern is: acknowledge it exists, put the detail behind a door.
- Detailed pricing logic, partner terms, tender response libraries
- Technical documentation for customers only
- Roadmap detail beyond what you present publicly
- Methodology depth (the summary is open, the step by step is not)
The public page can say what the asset is and how to request it. The asset itself sits behind authentication. This protects the document, and it also keeps your entity clean, because AI can still learn that the thing exists without reading what is inside.
Zone 3: Closed (should never reach an anonymous visitor)
This is where the audit finds the expensive stuff. Per the audit taxonomy, Critical findings are live credentials, API keys, private key material and hardcoded authentication values. High findings are internal or staging infrastructure referenced from public pages, administrative endpoints, source or configuration files, enumerable usernames, and documents whose filenames suggest they were never meant to be public. Medium findings are things like software version fingerprints, internal path fragments, document metadata, email addresses and authorship data. Many Medium items are intentional. They still deserve a second look.
Closed means closed at the server, not hidden at the page. If it was served once, assume it was read.
The Zone 3 list is short and boring, and that is the point. The Knowledge Exposure Audit deliberately does not report the normal, intended footprint of a working website. A long list of things that were already fine is noise. The goal is a small number of things worth acting on.
If you want to see how this works on your own domain, the Knowledge Exposure Audit is run personally, under a written scope request, on the exact domain you authorize. Book a call and we start with scope.
The aggregation problem nobody budgets for
Here is the part that makes this different from a normal content review. Individual facts pass every check. A job posting mentions an internal tool. A conference slide shows an architecture. A PDF carries an author name and a software version. A press release names a supplier. Each one is fine.
An AI system does not read them one at a time. It joins them. The result can be a picture of your internal stack, your vendor dependencies and your team structure that no one at your company ever decided to publish.
This is the governing idea behind the audit, and it is why I keep calling it knowledge sovereignty rather than data sovereignty. Data sovereignty asks where your model runs. Knowledge sovereignty asks whether your public footprint lets an outside system reconstruct what you never intended to package together. If that distinction interests you at national scale, I wrote about it in National AI Visibility, and the same logic applies to a ministry as to a manufacturer.
The risk is rarely one leaked document. It is ten innocent ones, read together.
Since you are still here: most enterprises are not leaking too much. They are exposing the wrong things and hiding the right ones. Your Dev team publishes a staging hostname in a JavaScript bundle while the legal team blocks every AI crawler on the site, and then everyone feels secure. The secret is out, and the brand is invisible. Both at once. I have seen this in companies, multiple times.
Designing the entity graph around the zones
An entity graph (the structured map of the people, products, places, organizations and claims that describe your company, and how they connect) is how AI systems decide what you are. Design it deliberately and it becomes your exposure control, not just your visibility tool. I covered the engineering side in the Entity Engineering Framework. Here is how it connects to exposure.
Step 1. Inventory the entities. List every entity you publish about: the organization, brands, products, executives, locations, technologies, partners, customers. Assign each a zone.
Step 2. One canonical source per Open entity. One page, one definition, consistent naming everywhere. When AI meets conflicting descriptions of the same thing, it picks one, or blends them. Neither is good. This is the same mechanism behind why good SEO content still fails in AI search, and the structural fix is page and heading discipline, which I laid out for developers in the section hierarchy blueprint.
Step 3. Declare the relationships you want. Customer to product, product to category, expert to topic, organization to country. Use structured data and clear on-page statements. If you do not declare relationships, AI guesses them.
Step 4. Withhold the relationships you do not want inferred. This is the new step. Ask for each relationship: is this a deliberate statement, or something a model could assemble from scattered clues? Supplier dependencies, internal system names and team structures are the usual suspects.
| Entity type | Typical zone | Publish | Keep out of public view |
|---|---|---|---|
| Organization, brands | Open | Legal name, scope, locations | Internal codenames |
| Products, services | Open / Controlled | Capabilities, categories | Pricing logic, roadmap detail |
| Executives | Open | Role, public bio | Direct contact paths beyond what is intended |
| Technology stack | Controlled / Closed | Only what customers need | Staging hostnames, internal paths, version fingerprints |
| Partners, suppliers | Controlled | Named strategic partners | Full supplier dependency map |
| Documents | Controlled / Closed | Titles of public assets | Internal files, metadata, draft versions |
Entity ambiguity is its own problem, and a nasty one. If you want the long version, see my piece on entity ambiguity resolution. The shortest summary: clean entities protect you in both directions.
Access patterns: what actually enforces a zone
This is where most teams get it wrong, because they confuse a request with a control.
| Mechanism | What it does | What it does NOT do |
|---|---|---|
| robots.txt rules per AI crawler | Tells compliant crawlers what to skip | Stop a crawler that ignores it, or hide a URL you also link publicly |
| noindex | Asks search engines not to list a page | Make the page private |
| Authentication | Stops anonymous access | Fix content that is already public and cached |
| Server-side configuration | Keeps values out of client code | Help if the value is already in a shipped bundle |
| Metadata stripping on documents | Removes author, path and software traces | Change what the visible text says |
| Removing links from sitemaps and navigation | Reduces discovery | Protect an unlinked URL that is still served |
Two points for the bot layer. First, AI crawlers are not one thing. Some collect training data, some fetch pages to answer a live question, some belong to search products. They have different user agents (GPTBot, OAI-SearchBot, ClaudeBot, PerplexityBot and Google-Extended are the names you will meet most often, but check each vendor’s current documentation because these change). Decide bot by bot, not with one blanket rule. Second, robots.txt is a polite request. It belongs in Zone 1 and Zone 2 policy. It does not belong anywhere near Zone 3.
So the rule is blunt. Zone 1 gets clarity. Zone 2 gets authentication. Zone 3 gets removed at the source. If a control relies on the visitor behaving, it is not a control.
How the audit runs
If you are wondering what an engagement looks like in practice, this is the sequence I use.
- Scope and written authorization. A written request naming the exact domain. Verbal go-aheads do not count. The audit stays inside that domain and never follows a link off it.
- Collection. A live crawl as an anonymous visitor would see it: pages, linked documents, client-side code. No logins, no special search engine access.
- Processing and classification. Every page is parsed and each match is scored Critical, High or Medium.
- Synthesis. A grounded review of what a competitor, journalist, hacker or AI system could plausibly infer, strictly from what was found. Nothing invented.
- Delivery. One confidential report to the named recipient. Collected content is not retained afterward.
Each finding carries the exact source URL, the detected value, the exposure type, the reasoning for the flag, whether there is any legitimate public need, and a specific next action. A finding is evidence, not a warning.
What gain can you expect? Honest answer: it depends on how old and how messy the domain is. As a planning assumption (mine, not a benchmark), a mid-size enterprise domain tends to need roughly two to six weeks of remediation work after the report, mostly in web development and content operations. Not enough available data to quote a verified industry average of findings per domain. What I can say is the audit is built to return a short list, not a long one, and the cheapest wins are almost always in client-side code, old documents and forgotten staging references.
Why enterprises struggle to own this
Inside a large organization, this question falls between four teams. Security owns breaches. SEO owns visibility. Legal owns policy. Communications owns the message. Each assumes the intersection belongs to someone else. I have sat in that room, and the usual outcome is that nobody owns it until something goes wrong.
Three patterns repeat. Migrations leave old environments referenced from live pages (my post-migration recovery guide covers the SEO side of why rebuilds create these leftovers). Visibility programs optimize for more content with no review for what the content reveals, which is a symptom of SEO treated as a channel instead of a system. And ownership of AI representation is undefined, a problem I explored in AI misrepresentation risk.
Related ground: if your documents carry proprietary methodology, read the AI intellectual property guide. If you are weighing where AI infrastructure should physically live, the vulnerability of centralized data centers and the hybrid SaaS and sovereign fallback pieces go deeper. And the structural layer that ties visibility and exposure together is described in Enterprise Visibility Architecture.
What to do this month
- Ask public AI about yourself. Use several assistants, ask who you are, what you sell, who your suppliers and customers are, what technology you use. Save the answers. Note anything that surprises you.
- Sort your entity list into zones. Open, Controlled, Closed. A spreadsheet is enough.
- Search your own client-side code and documents for hostnames, paths, keys and author metadata. If you find a key, rotate it first and ask questions later.
- Write bot-by-bot crawler rules for Zone 1 and Zone 2, and stop pretending robots.txt protects Zone 3.
- Fix the Open zone. One canonical page per entity, consistent names, declared relationships.
- Assign an owner. One named person who answers for what AI learns about the organization. Without this, steps one to five decay.
Doing it yourself is realistic for a small domain. For an enterprise footprint, with subdomains, legacy documents and several CMS platforms, an independent outside-in review is faster and, frankly, more honest, because insiders stop seeing their own habits. If you want that review, start with a free assessment in the AI Assessment Center or read how my AI knowledge control and governance offer is structured, then contact me with the domain you want in scope.
Frequently asked questions
It is a structured review of what an outside AI system could retrieve or reconstruct from your public footprint. It does not test for break-ins. It examines authorized, public content and asks whether any of it, alone or combined, reveals what you never meant to share.
No. Most public information is supposed to be public. A finding only exists where the pattern suggests there is no obvious legitimate reason to serve that content to an anonymous visitor. Public is not the same as vulnerable.
Your identity, your products and services, your published positions, the proof points you are comfortable being quoted on, and the corrections to questions where AI currently gets you wrong. That is the Open zone.
Controlled material (detailed pricing logic, customer-only documentation, roadmap depth, methodology step by step) belongs behind authentication. Closed material (credentials, internal hostnames, configuration files, source files, enumerable usernames) should never reach an anonymous visitor.
Not by itself. robots.txt is a request that compliant crawlers follow, and it does not secure a URL that is still served. It also reduces your visibility if applied as a blanket rule. Decide crawler by crawler, and enforce Zone 3 at the server.
The entity graph decides what AI understands about you. Declare the relationships you want, keep one canonical source per Open entity, and check which relationships a model could infer from scattered clues that you would rather not state.
Shadow AI monitoring covers what your people send into AI tools. Knowledge exposure covers what AI systems can learn from your public content, from the outside, without anyone inside doing anything.
My planning assumption is roughly two to six weeks for a mid-size enterprise domain, mostly in web development and content operations. Not enough available data for a verified benchmark.
Under a written scope request naming the exact domain. It results in one confidential report to the named recipient, and collected content is not retained after the engagement.
This article was researched and drafted with the assistance of AI tools and reviewed and edited by author prior to publication.
