

In This Article
Somebody on your team typed your company name into ChatGPT, read the answer, and went quiet.
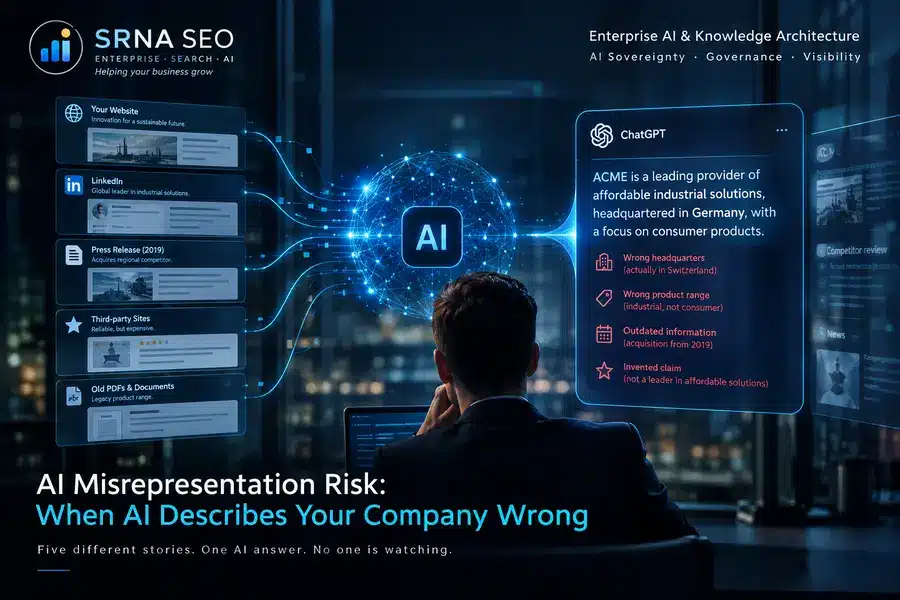
That silence is AI misrepresentation risk (the chance that an AI system describes your organization in a way that is wrong, outdated or simply invented, while nobody inside the company is watching). And here is the one statement I want you to keep from this article: most AI misrepresentation is not the model lying, it is your company telling five slightly different stories and the model averaging them.
I have sat inside global enterprises for years, and the pattern is boring and familiar. The website says one thing, the LinkedIn page another, the 2019 press release a third. Nobody owns the full picture. Then AI arrives, reads all of it, and gives your future customer a confident summary that no one in your company would sign.
What AI misrepresentation risk actually is
AI misrepresentation happens when an AI system (ChatGPT, Gemini, Perplexity, Copilot and similar) produces an answer about your organization that diverges from reality. The answer sounds sure of itself. That is the dangerous part.
In practice I see five types:
- Wrong facts. Wrong headquarters, wrong product range, wrong leadership, wrong numbers.
- Wrong category. You compete on reliability, the answer files you under cheap. You are modern, the answer files you under legacy.
- Stale story. A rebrand, an acquisition or a pivot from years ago that AI still treats as current.
- Borrowed identity. Another company, product or person with a similar name gets mixed into your profile. This is an entity problem (an entity is a distinct thing, like a company or product, that AI systems try to tell apart from everything else). I wrote about it in entity ambiguity resolution and conflicting signals.
- Invented claim. A capability, certification or policy that does not exist. This is the classic hallucination, and I cover the content side in LLM hallucination and content risk.
Notice that only the last one is pure invention. The other four are your own messy signals coming back to you, wearing a nicer suit.
Why it happens (and why it is mostly an inside job)
AI systems build their picture of you from whatever they can find: your site, your profiles, third-party pages, old articles. Some answers come from what the model learned during training. Others come from the retrieval layer (the part of an AI search tool that pulls live web sources before it writes the answer). Both can go wrong, in different ways.
So what do they find? In large organizations, usually contradictions. Different regions describe the company differently. Product pages are updated, old PDFs stay online. Subsidiaries use their own wording. When signals conflict, the model does not pause and ask your communications director. It picks a likely version.
And when your official content is thin, third parties fill the gap. A review site, an old news item, a competitor comparison page. They become your voice, and you never approved the script.
If you want the wider view of this problem, AI invisibility is an enterprise risk, not just an SEO problem covers the absence side. Misrepresentation is its louder cousin, because here AI does show up. It just says the wrong thing.
The Air Canada lesson, and where it stops
The case everybody quotes is Air Canada. A customer received wrong advice from the airline’s own chatbot, acted on it, and a Canadian tribunal later held the company liable for negligent misrepresentation. The principle was simple: you answer for what your chatbot tells people.
But look at the limit of that case. It was the airline’s own chatbot. When ChatGPT or Gemini misdescribes you, the question of who is responsible is much less settled, and I am not a lawyer. Not enough available data to give you a clean answer. What I can say is that I explored the ownership question in AI accountability: who is responsible for AI representation, and the honest summary is that the law is behind the problem.
What this costs you
Most of the cost is invisible, and that is exactly why it survives. The AI sessions where your buyers form their first impression do not show up in your analytics. Nobody files a ticket saying “ChatGPT described us as a budget vendor.”
Here is where I would look first:
- Shortlists. If AI puts you in the wrong category, you are not on the list before procurement even starts. I wrote about this in AI is influencing procurement before procurement starts.
- Sales conversations. Your team spends the first twenty minutes correcting something the prospect “learned” from an answer engine. (Twenty is my feel from client work, not a measured benchmark.)
- Reputation with non-buyers. Journalists, analysts, candidates and regulators ask AI too.
I have no honest universal figure for the revenue impact. Anyone who gives you one without your data is selling something. If you want to put a first estimate on the table for your own board, the AI Visibility Cost of Inaction Calculator is a starting point, not a verdict.
This is not a PR crisis plan for deepfakes, though those are real. It is not a prompt trick you can apply once and forget, because you do not control the prompts your buyers type. It is not a tool purchase, either. A dashboard can show you the wrong answer, but it cannot tell you why your company produces contradictory signals. And it is not a guarantee of a perfect answer in every AI system, because nobody can promise that.
Misrepresentation is a governance problem that shows up as a search problem.
Where I can help?
If you are an SEO Manager, Head of Digital or VP reading this and thinking “I have no idea what AI says about us,” that is the right place to start. My Free Assessment Center gives you a first read, and the Knowledge Exposure Audit goes deeper into what AI systems can actually say about your organization. Both come from inhouse work, not agency theory.
How I would fix it: six steps
1. Measure the answers, not the rankings. Ask AI systems three kinds of questions: direct brand questions, category questions (“who are the leading providers of X”), and comparison questions against your competitors. The same fact can come back different depending on how the question is phrased. Write down what you get, system by system. The AI Visibility Inspector (my diagnostic tool for how AI systems see a website) and NovaX (my AI Visibility Intelligence Platform) are built for this kind of check, but a spreadsheet and an afternoon will already show you something uncomfortable.
2. Sort the errors by type. Use the five types above. A wrong category needs a different fix than a stale story. If you treat them all as “hallucinations,” you will fix none of them.
3. Trace each error to a source. Where does the wrong version live? An old page, a conflicting profile, a third-party listing, a missing page? This step is slow and unglamorous. It is also the whole job.
4. Fix the ground truth first. Pick one authoritative version of each core fact (what you do, where, for whom, since when) and make every owned property agree with it. Then clean up the conflicting signals. My Entity Clarity Index is built around exactly this question of how clearly your organization reads as one entity.
5. Give it an owner. Marketing assumes legal has it. Legal assumes security has it. Security assumes marketing has it. Somebody needs a name next to this risk, a review cadence and an escalation path. The AI Visibility Governance Blueprint lays out how I would structure that.
6. Re-test on a schedule. Answers change after model updates and content changes. I would run the same query set monthly (my preference, not a rule) and log the differences. Also read AI correction rights so you know what you can and cannot ask a platform to change. Spoiler, it is less than you want.
The estimated gain
Honestly? Not enough available data for a universal range. Results depend on how contradictory your signals are today, how many regions and subsidiaries publish about you, and which AI systems your buyers use.
What I can say from client-side work is directional. The first pass, finding and removing contradictions in your own content, usually produces the biggest visible shift in how you are described. Whether that takes weeks or months depends on how fast your organization can actually agree on one story. Believe me, that is the slow part, not the SEO.
Who owns AI misrepresentation risk
If you remember nothing else, remember this: a risk without an owner is not managed, it is just observed. So before you buy tools or rewrite pages, answer one question in writing. Who is accountable when AI describes our company wrong?
Talk to me
If you want help working out where your signals conflict and who should own the fix, look at my Enterprise Search Advisory or contact me directly. I work with SEO Managers, Heads of Digital and C-suite teams who need an adviser who has been inside a global company, not a slide deck.
FAQ
It is the chance that an AI system describes your organization in a way that is wrong, outdated or invented, without anyone inside your company noticing in time.
No. Hallucination (an invented claim) is one of five types I see. The others are wrong facts, wrong category, stale story and borrowed identity, and four of the five usually trace back to conflicting or weak signals in your own content.
AI builds its picture from your site, your profiles, third-party pages and older material. When these conflict, or when your own content is thin, the system picks a likely version, and third parties can end up speaking for you.
In the Air Canada case, a tribunal held the company liable for negligent misrepresentation over its own chatbot’s advice. Whether the same applies to third-party AI systems describing you is not settled, and I am not a lawyer. Not enough available data for a firm answer.
Ask direct brand questions, category questions and comparison questions across several AI systems, then record the answers. The same fact can change depending on phrasing.
Not reliably. Your stronger lever is fixing the sources the AI relies on. I cover the limits in my article on AI correction rights.
One named person or function, with a review cadence and an escalation path. When marketing, legal and security each assume another team has it, nobody does.
Not enough available data for a universal range. It depends on how contradictory your signals are today and how many teams publish about you.
This article was researched and drafted with the assistance of AI tools and reviewed and edited by author prior to publication.
