

In This Article
This research is part of the Building A Europe AI Can See series, which also includes National AI profiles of Austria, Belgium, Croatia, Cyprus, Czechia, Denmark, Estonia, Finland, France, Germany, Greece, Hungary, Ireland, Norway, Sweden, United Kingdom. Same Frameworks and AI Visibility Inspector were used in all researches.
The five audited Dutch pages average 61.2 on the AI Retrieval Index (the 0 to 100 score from the AI Visibility Inspector that rates how easily AI engines can parse, attribute and cite a page). That puts the Netherlands third of the nine countries compared so far, behind Sweden (68.8) and the United Kingdom (64.4), and ahead of Norway (58.0), Hungary (55.8), Switzerland (52.6), Ireland and Germany (both 51.8) and Greece (49.4). The main finding is the spread. Three pages grade C and two grade D, a gap of 24 points between the best and the worst. In Switzerland the same gap was 5 points. All five Dutch pages score a perfect 100 on structure, and not one of them declares a Person or Article schema block.
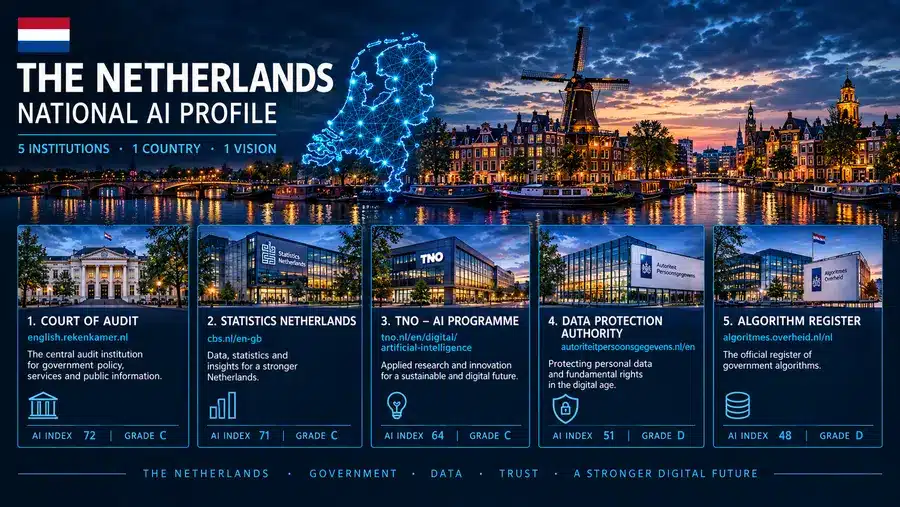
This profile covers the English entry points of the Court of Audit, Statistics Netherlands and the Dutch Data Protection Authority, the AI programme page of TNO, and the Dutch language page of the government algorithm register.
The Profile in One View
| Page | AI Retrieval Index | Grade | Structure | Depth | Schema |
|---|---|---|---|---|---|
| Algemene Rekenkamer (english.rekenkamer.nl) | 72 | C | A | C | D |
| Statistics Netherlands (cbs.nl/en-gb) | 71 | C | A | C | D |
| TNO, AI programme (tno.nl/en/digital/artificial-intelligence) | 64 | C | A | B | D |
| Dutch Data Protection Authority (autoriteitpersoonsgegevens.nl/en) | 51 | D | A | C | F |
| Algorithm register (algoritmes.overheid.nl/nl) | 48 | D | A | C | F |
| Average | 61.2 |
Two groups show up straight away. The Court of Audit, Statistics Netherlands and TNO sit at 64 to 72 with a D grade on Schema at worst. The Data Protection Authority and the algorithm register sit at 48 and 51 with an F on Schema. And here is the part I find uncomfortable (my opinion, not a finding): the two weakest pages belong to the bodies you would expect to be most aware of how automated systems read information. The algorithm register is literally a public list of government algorithms, and its own page declares no structured data at all.
Perfect structure with an empty identity layer is not a neutral state. It is a page that is easy to read and impossible to attribute.
How the Netherlands compares with the five countries:
| Dimension | Netherlands (range) | UK | Sweden | Norway | Ireland | Germany | Switzerland |
|---|---|---|---|---|---|---|---|
| Structural Integrity | 100.0 (100) | 96.0 | 100.0 | 92.0 | 86.0 | 74.0 | 99.0 |
| Data Extractability | 68.2 (65 to 75) | 73.4 | 83.0 | 71.4 | 73.2 | 68.4 | 77.0 |
| Entity Clarity | 52.0 (40 to 65) | 57.0 | 49.0 | 52.0 | 46.0 | 55.0 | 44.0 |
| Schema & Metadata | 31.0 (15 to 50) | 41.0 | 38.0 | 31.0 | 26.0 | 31.0 | 23.0 |
| Freshness & Decay | 43.0 (0 to 93) | 43.2 | 65.0 | 31.8 | 14.2 | 21.4 | 0.0 |
| AI Retrieval Index | 61.2 (48 to 72) | 64.4 | 68.8 | 58.0 | 51.8 | 51.8 | 52.6 |
The Netherlands ties Sweden on structure, and has the lowest extractability of the six countries in this table (68.2, just under Germany at 68.4). Freshness lands almost exactly on the UK (43.0 against 43.2), but the average hides a range from 0 to 93. Two pages have no machine-readable date at all, and the Court of Audit scores 93.
How the Five Engines Read the Dutch Pages
| Page | Perplexity | ChatGPT | Claude | Gemini | Copilot |
|---|---|---|---|---|---|
| Algorithm register | 40 (~31%) | 68 (~41%) | 73 (~45%) | 31 (~20%) | 43 (~26%) |
| Data Protection Authority | 43 (~27%) | 71 (~49%) | 76 (~46%) | 34 (~15%) | 58 (~34%) |
| TNO | 62 (~44%) | 74 (~50%) | 77 (~46%) | 52 (~17%) | 58 (~34%) |
| Statistics Netherlands | 66 (~63%) | 76 (~50%) | 81 (~51%) | 64 (~20%) | 74 (~47%) |
| Court of Audit | 66 (~51%) | 76 (~50%) | 81 (~51%) | 64 (~16%) | 74 (~47%) |
| Average | 55.4 (~43.2%) | 73.0 (~48.0%) | 77.6 (~47.8%) | 49.0 (~17.6%) | 61.4 (~37.6%) |
Claude (77.6) and ChatGPT (73.0) score the Dutch pages highest, as they did in Switzerland (77.2 and 74.2). The difference is in the other three engines. Perplexity averages 55.4 here against 46.4 in Switzerland, Copilot 61.4 against 52.0, and Gemini 49.0 against 34.8. The estimated citation share tells the same story: about 43% for Perplexity here, about 32% in Switzerland.
My reading is that engines which reward hierarchy and topical depth treat the Netherlands and Switzerland the same, because structure is strong in both. The engines that lean on structured data, dates and authorship signals separate the two countries, because the Dutch set has some of those signals and the Swiss set had almost none. That is an interpretation of the audit output, not a tested cause.
Claude and ChatGPT read the Dutch pages well. Gemini still barely cites them, at about 18% on average.
What the Five Audits Reveal
Structure is solved. Every page scores 100, with a single H1, logical nesting and balanced headings. This is the layer Dutch institutions got right.
Extractability is uneven and low. Scores run 65 to 75 (average 68.2). The gap is mostly image alt text. The Inspector flags missing alt text on 2 images at the Data Protection Authority, 10 at TNO, 12 at Statistics Netherlands and 12 at the Court of Audit, 36 in total (the algorithm register raised no alt text warning). Alt text coverage is reported as 82% at the Data Protection Authority, 29% at TNO, 20% at Statistics Netherlands and 8% at the Court of Audit.
Entity clarity is split in half. Statistics Netherlands and the Court of Audit score 65. The other three score 40 to 45. The difference is a schema block that names the organization, which only the first two have in some form.
Schema is the weak layer. Three of five pages show no JSON-LD at all (algorithm register, Data Protection Authority, TNO). Statistics Netherlands has two blocks, one valid Organization block (5 of 8 fields: name, URL, sameAs, logo, address) and one WebSite block that is invalid because it lacks a name. The Court of Audit has 14 blocks, all valid: a WebSite block, a GovernmentOrganization block and 12 ImageObject blocks. Yet the Inspector reports Organization, Person and Article as not detected for the Court of Audit, so its entity connectivity stays at 0. Whether the tool should count GovernmentOrganization as an Organization is a question for the tool, and I list it under Boundaries below.
Freshness has the widest range of any dimension. The algorithm register and the Data Protection Authority score 0. TNO scores 57 and Statistics Netherlands 65, but both have dates only in text or meta tags, not in JSON-LD. The Court of Audit scores 93 and raised no freshness warning.
The trust layer is nearly empty. Entity connectivity averages 4.0 (only Statistics Netherlands is above zero, at 20). Knowledge graph anchoring is 0 on four pages and 100 on one: Statistics Netherlands, anchored to three knowledge graph sources. E-E-A-T density averages 8.0, and semantic richness 39.8.
One more thing about that Statistics Netherlands page. It is the only page with knowledge graph anchoring, and it has the highest Perplexity citation estimate in the set (about 63%), with the Inspector noting “core citation signals detected”. One page proves nothing. But I would test it first.
Query eligibility sits at about 53% across 136 generated queries. Statistics Netherlands (56.1%) and the Court of Audit (55.8%) are highest, the Data Protection Authority (49.5%) lowest.
Page Profiles
Algorithm register (algoritmes.overheid.nl/nl)
Score 48, grade D. The only page audited in Dutch, and the lowest in the set. AI models parse it as being about “Het algoritmeregister van de Nederlandse overheid”, which is correct. No JSON-LD, no canonical URL, no machine-readable date, and entity connectivity, knowledge graph anchoring and E-E-A-T density all at 0. The Inspector counts 395 words and advises expanding to 600 or more. Only 9 queries were generated, all informational. Several are interface artefacts (“What is provincies?”, “What is organisaties?”), and two entities are detection errors (“Zoeken Bekijk”, “Brabant Zivver”). What it means for AI systems: the page says what it is, in the language of its readers, and says nothing about who publishes it.
Dutch Data Protection Authority (autoriteitpersoonsgegevens.nl/en)
Score 51, grade D. Parsed as being about “Home”, which is the whole problem in one word. No schema, no dates, and no meta description. Two images lack alt text. It has 25 queries and the lowest eligibility in the set (49.5%). Some are real headlines (a warning on smart glasses, a fine of nearly 825 million euros for Uber, advice to Twitch users on opting out of data sharing for AI). Others are navigation labels read as questions (“What is hoofdnavigatie?”, “What is footernavigatie?”). The Inspector does detect “Autoriteit Persoonsgegevens” as an organization, but with no schema behind it, the score on that entity is 68% clarity. What it means for AI systems: the content is current and substantive, and the engine cannot tell. Freshness 0 on a page with that headline mix is a missed opportunity.
TNO (tno.nl/en/digital/artificial-intelligence)
Score 64, grade C, the only AI-specific page in the set. AI models parse it as “Artificial intelligence research programmes”. Depth is the best of the five (B). No JSON-LD, 10 images without alt text (29% coverage), and dates only outside JSON-LD. Detected content includes the GPT-NL sovereign language model, an AI Oversight Lab, the Netherlands’ first AI Factory, and a named programme director. None of it is tied to a Person block. The Inspector reads the organization as “tno.nl/en” instead of TNO, which is an entity naming problem worth fixing on its own. Four “FAQ” queries at 60% turn out to be event fields (“Startdatum”, “Locatie”, “Informatietype”), not real questions. What it means for AI systems: this page has the most AI-relevant substance in the Dutch set and the least machine-readable proof of who stands behind it.
Statistics Netherlands (cbs.nl/en-gb)
Score 71, grade C. Parsed as “Statistics Netherlands”. The only page with a valid Organization block, knowledge graph anchoring at 100, and the highest query eligibility (56.1% across 36 queries). It also has 12 images without alt text (20% coverage), a broken WebSite block, and no Person or Article schema. The queries are mostly recent news headlines (inflation, unemployment, bankruptcies, housing prices). What it means for AI systems: the closest thing to a complete entity record in this set, and a data publisher whose page is still read through its news feed.
Court of Audit (english.rekenkamer.nl)
Score 72, grade C, the top page. 14 valid schema blocks and the best freshness score (93). Also no meta description, 12 images without alt text (8% coverage, the lowest), and Organization, Person and Article all reported as not detected. Detected queries include headlines on military mobility, quantum technology and anti-money laundering. One entity is read as “Netherlands Court”, not “Algemene Rekenkamer” (the latter is classed as an emerging concept at 48% clarity). What it means for AI systems: this is the page with the most schema and the most visible naming problem. It has 12 ImageObject blocks, and 12 images with no alt text.
| Page | AI Retrieval Index | Images missing alt text (coverage) | Entity graph stability | E-E-A-T density | Semantic richness | Queries (avg eligibility) |
|---|---|---|---|---|---|---|
| Court of Audit | 72 | 12 (8%) | 69 | 0 | 53 | 29 (55.8%) |
| Statistics Netherlands | 71 | 12 (20%) | 54 | 18 | 46 | 36 (56.1%) |
| TNO | 64 | 10 (29%) | 65 | 7 | 45 | 37 (50.7%) |
| Data Protection Authority | 51 | 2 (82%) | 56 | 15 | 31 | 25 (49.5%) |
| Algorithm register | 48 | none flagged | 61 | 0 | 24 | 9 (51.4%) |
What This Means
The Dutch set is not one profile. It is two. One group (Court of Audit, Statistics Netherlands, TNO) has some schema, some dates and a usable entity layer. The other (Data Protection Authority, algorithm register) has none of them. That is a different result from Switzerland, where all five pages behaved alike.
And the fixes are small. Based on the Inspector’s own recommendations, the common list is: JSON-LD with Article and Person blocks where authors are named, an Organization block with sameAs links (Wikipedia or Wikidata), datePublished and dateModified in JSON-LD, alt text for the 36 flagged images, a meta description for the Data Protection Authority and the Court of Audit, a canonical URL for the algorithm register, and a valid name in the Statistics Netherlands WebSite block. Honest numbers on the gain: Not enough available data to state a verified uplift. What the dataset does show is that the 24-point gap between best and worst page sits in schema, entity and freshness layers, which are template-level work, not content rewrites.
If you want this done on your own pages, book a call and tell me which pages you want in scope.
Scope and Method
Five pages were audited with the AI Visibility Inspector (version 1.9.3) and Srna Frameworks on 28 October 2026:
- https://algoritmes.overheid.nl/nl (algorithm register)
- https://autoriteitpersoonsgegevens.nl/en (Dutch Data Protection Authority)
- https://www.tno.nl/en/digital/artificial-intelligence/ (TNO)
- https://www.cbs.nl/en-gb (Statistics Netherlands)
- https://english.rekenkamer.nl/ (Court of Audit)
Each audit reports an AI Retrieval Index and grade, Structure, Depth and Schema sub-grades, five scored dimensions, five engine scores with estimated citation shares, a Schema Intelligence section, query eligibility, and entity graph stability.
Boundaries
What this research is NOT: it is not a ranking of Dutch institutions, and it does not measure how good their content is. It measures how machine-readable five pages were on one day.
- Five pages is five pages. Each is one entry per institution, four in English and one in Dutch. Other languages, subpages and PDFs were not audited, and the algorithm register page cannot be compared like for like with an English homepage.
- Findings reflect 28 October 2026. Headlines and news items change daily.
- Averages are simple means of five pages. Comparison figures come from earlier country profiles.
- The Statistics Netherlands and Court of Audit pages return identical engine scores (66, 76, 81, 64, 74) even though their dimension scores differ. The Inspector does not explain this.
- The Court of Audit has 14 valid schema blocks but reports Organization as not detected. The Inspector does not appear to count GovernmentOrganization as an Organization. I report what the tool reports.
- The Inspector does not run scripts, so JavaScript-added markup would not appear. It reports JSON-LD only.
- Date detection counts machine-readable signals only.
- Automated entity and query detection produces artefacts (navigation labels read as questions, “tno.nl/en” as an organization, “Conversion Rate” as a topic on a statistics office). Generic content gap lists were not interpreted.
- Citation figures are the Inspector’s estimates, not observed engine citations.
- Named entities and headlines are reported as detected and were not independently verified.
Calculate Your Potential Exposure
Reading poorly to AI has a cost. If you want to put a number on it for your own site, use the AI Visibility Cost of Inaction Calculator and enter your own sessions, conversion rate and revenue per conversion. The output is a strategic estimate, not a forecast.
Frequently Asked Questions
The five audited Dutch pages average 61.2 on the AI Retrieval Index, third of the nine countries compared so far, behind Sweden (68.8) and the United Kingdom (64.4).
The Court of Audit scored highest (72, grade C) and the government algorithm register lowest (48, grade D). The gap is 24 points.
Schema and identity signals. Structure scores 100 everywhere, but no page declares a Person or Article block, three of five have no JSON-LD at all, and entity connectivity averages 4.0.
Claude (77.6 average) and ChatGPT (73.0). Gemini scores lowest at 49.0, with an estimated citation share of about 18%.
No. Citation figures are the Inspector’s estimates, not observed citations. Statistics Netherlands, the only page with knowledge graph anchoring, has the highest Perplexity estimate (about 63%), but that is one page.
JSON-LD with Organization and sameAs links, dates in JSON-LD, alt text for the 36 flagged images, a meta description for the two pages missing one, a canonical URL for the algorithm register and a valid name in the Statistics Netherlands WebSite block.
This article was researched and drafted with the assistance of AI tools and reviewed and edited by author prior to publication.
