
In This Article
You published your best research, an AI system used it last Tuesday to answer a buyer’s question, and nobody asked, nobody paid, and your name may not even be in the answer.
That is the real situation with intellectual property in AI, and here is the most important thing I can tell you: your IP is protected in AI only as far as you can document it, signal it and enforce it. In my experience, most enterprises do none of the three. They own the rights. They just never made those rights visible to a machine.
What Is Intellectual Property in AI?
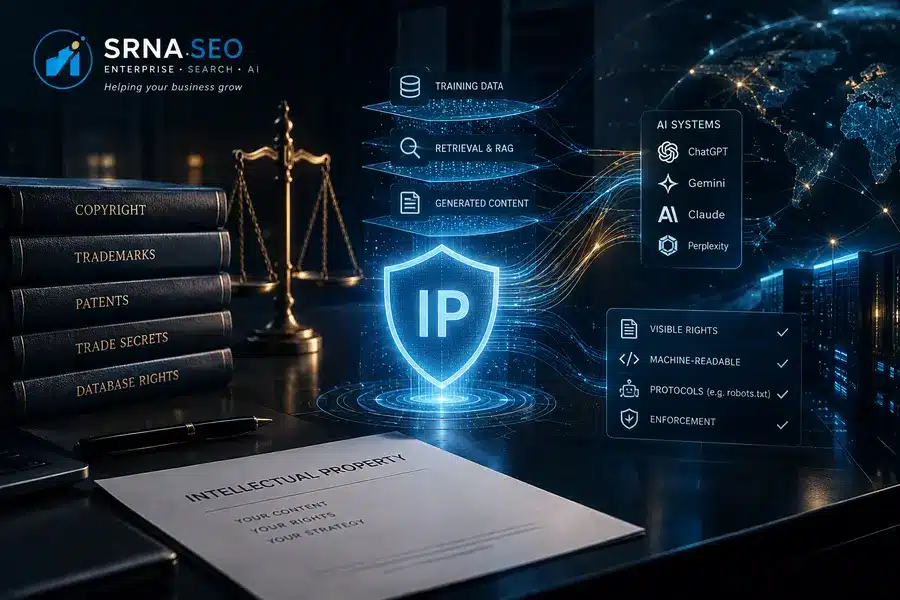
Intellectual property in AI is the set of legal rights (copyright, trademarks, patents, trade secrets and database rights) that decide who owns three different things: the content AI systems are trained on, the content they retrieve and cite when they answer, and the content they generate.
Three layers, three different legal questions. Mixing them up is the most common mistake I see in executive discussions.
| Layer | What happens | Main legal question |
|---|---|---|
| Training | Your pages are collected and used to build or tune a model | Is copying for training allowed without permission? |
| Retrieval and citation | An AI system fetches your page at answer time and uses it in a response | Is that reproduction, and who gets credit? |
| Output | The AI produces text, images or code for you | Can anyone own it? |
The U.S. Copyright Office has said that building a training dataset from copyrighted works clearly involves the right of reproduction, and that retrieval-augmented generation (RAG, where the system fetches live content to feed its answer) also involves making copies at generation time. The same office declined to set one rule for fair use in training. It said each case has to be judged on its facts. So nobody can promise you a clean answer today, and be careful with anyone who does.
What Courts Have Actually Decided So Far
Less than you would hope. But a few things are clear enough to plan around.
Bartz v. Anthropic. In June 2025 a U.S. district judge found that training a large language model on lawfully acquired books was fair use, because the use was transformative. The same judge refused that defense for downloading millions of books from pirate libraries and keeping them. Anthropic then agreed to a settlement of at least $1.5 billion in September 2025, and the court later approved it.
Kadrey v. Meta. Two days after Bartz, another judge in the same district found Meta’s training use fair use on the theory the authors presented. The case is still alive on a separate claim about uploading works through BitTorrent.
Thaler v. Perlmutter. On March 2, 2026 the U.S. Supreme Court declined to review the case. That leaves in place the rule that a work generated entirely by AI, without meaningful human authorship, cannot be registered for U.S. copyright.
The lesson I take from the first two cases is simple. How the copy was obtained mattered as much as what was done with it. Lawfully accessed content was treated very differently from pirated content.
What about ordinary corporate web pages scraped for training? I could not verify a final ruling that settles it. So I will not pretend there is one.
The European Position (Where Most of My Clients Operate)
As a European, this is the part I find most practical, because the EU gave rightsholders a lever.
Article 4(3) of the DSM Copyright Directive (the 2019 EU copyright reform) allows commercial text and data mining of lawfully accessible content, unless the rightsholder has reserved their rights in a machine-readable way. Article 53(1)(c) of the EU AI Act then requires providers of general-purpose AI models to have a copyright policy that identifies and respects those reservations.
Three things follow from that:
- A reservation only works if a machine can read it. A line buried in a PDF is a weak signal.
- The GPAI Code of Practice (the voluntary code the Commission approved as a way to show AI Act compliance) commits signatories to respect robots.txt and other appropriate machine-readable protocols.
- The Commission opened a consultation in late 2025 to build an agreed list of those protocols. I would watch that list, because it will tell you which signals actually count.
There is a gap, and I want to be direct about it. Legal commentators point out that a third party who scrapes and passes data to a model provider is not itself bound by Article 53. So your reservation reaches the model provider, but it may not reach every scraper upstream. Not a reason to skip it. A reason to stack it with other measures.
If your content is sourced or served across borders, my article on national information sovereignty covers why the jurisdiction question keeps coming back.
Where I Would Start: Find Out What You Are Exposing
Before you write a single robots.txt rule, you need to know what AI systems can already see, quote and get wrong about you. That is the point of the Knowledge Exposure Audit (my audit of what knowledge your organization exposes to AI systems), and I explain why security reviews miss it in Knowledge Exposure: The Question Your Security Audit Never Asks.
If you want a quick first look, the AI Visibility Inspector (my tool for checking how AI systems see a site) is the lighter entry point. And if you would rather talk it through with someone who has done this inside global enterprises, that is exactly what the Enterprise Search Advisory is for.
The Contrarian Part: Blocking Every AI Bot Is Not IP Protection
Blocking every AI crawler is not IP protection. It is self-inflicted invisibility.
I see this reaction in boardrooms right now. Someone reads a scary article, legal asks IT to block everything with “AI” in the name, and three months later the same company asks why no AI system mentions it. The two are connected.
The reason is that crawlers do different jobs. Some collect data to train models. Others build the search index an AI product answers from. Others fetch one page because a user asked. Block the first group and you reserve your rights. Block the second and third and you remove yourself from answers. I go deeper on this in what ChatGPT Search, Perplexity, Gemini, Copilot and Meta AI actually do to your enterprise visibility.
Here is how I think about the common ones. Names and roles change, so verify each against the operator’s own documentation before you touch robots.txt.
| Crawler | Operator | Main job | My default view |
|---|---|---|---|
| GPTBot | OpenAI | Collects content for model training | A rights decision, make it deliberately |
| OAI-SearchBot | OpenAI | Builds the index behind ChatGPT search | Usually allow, it feeds visibility |
| ChatGPT-User | OpenAI | Fetches a page when a user asks | Usually allow |
| ClaudeBot | Anthropic | Collects content for model training | A rights decision |
| Google-Extended | Control token for Gemini training and grounding | A rights decision, it does not control Google Search | |
| CCBot | Common Crawl | Builds an open dataset many models use | A rights decision |
| PerplexityBot | Perplexity | Builds Perplexity’s search index | Usually allow, it feeds visibility |
And one more honest point. robots.txt is a request, not a lock. Well-behaved bots follow it. Others do not.
A Practical Protection Stack
This is the order I would work in. Not legal advice, so involve your counsel at step 2 and step 5 at the latest.
- Document authorship and dates. Keep drafts, version history and publication records for your key assets. If you ever need to prove a piece is yours and when it existed, this is your evidence.
- Reserve your rights in plain language. Put a clear rights reservation and an AI-use clause in your terms. In the EU this supports your Article 4(3) position, though a plain-text clause alone is a weaker signal than a machine-readable one.
- Set crawler rules deliberately. Decide per bot, using the table above, which ones you allow for visibility and which ones you refuse for training.
- Add machine-readable signals. Use the protocols the EU process recognizes as it settles. The TDM Reservation Protocol (TDMRep) is one that gets mentioned in this discussion, and I would check the Commission’s list before betting on any single format.
- Check registration options. In the U.S., registering a copyright is generally the gate to suing, so talk to counsel about which assets deserve it.
- Monitor what AI says about you. Protection without monitoring is a policy nobody checks. NovaX (my AI visibility intelligence platform) is built for tracking where and how AI systems cite you.
- Decide your licensing position. Some publishers license content. Reddit’s reported deal with Google, around $60 million a year, shows there is a market, but that number is reported, not confirmed by me, and most companies are not Reddit.
- Give it an owner. Someone has to own AI representation. My AI Visibility Governance Blueprint shows how I set that up, and AI accountability: who is responsible for an AI’s representation explains why the answer is rarely obvious.
When AI Cites You (or Gets You Wrong)
Scraping is only half the story. The other half is being cited, summarized and sometimes misquoted without a click ever reaching you. I covered who gets credit in Zero-Click Synthesis: Who Gets Credit for Your Facts.
Then there is the harder question: can you make an AI correct a false statement about your company? My answer in AI Correction Rights is that it is limited and uneven today. And conflicting signals about your brand make it worse, which is why I wrote about entity ambiguity resolution. Clean, consistent entity data is also part of IP defense, because a machine that cannot tell who owns a claim will attribute it to someone else.
Who Owns What AI Creates for You?
Short answer for the U.S.: a work generated entirely by AI has no copyright protection. Where there is clear human creative contribution, protection may cover the human-authored parts only. Other jurisdictions go further. The UK grants copyright to the person who made the arrangements for creating a computer-generated work, and China has recognized AI-generated images as eligible in some cases.
So if your team uses AI to draft whitepapers, code or designs, record where the human decisions were made. Prompts, edits, selection, structure. That documentation is your claim.
I follow the same rule on this site. Every article I publish carries a disclosure that AI tools assisted the drafting and that I reviewed and edited it before publication. The EU expects that kind of transparency, and I would rather say it than be asked.
This is not legal advice, and I am not a lawyer. It is also not a promise that opting out stops your content being used. It does not replace a copyright registration strategy, a licensing negotiation or a lawsuit. And it is not a call to hide your content from AI. If you want to stay invisible, this article will cost you visibility. If you want control, read on.
Estimated Gain After Implementation
I have no measured data showing how much a rights reservation reduces AI use of your content. Not enough available data, and I will not invent a percentage.
What I can give you is an effort estimate from my own audit work: a first pass of steps 1 to 4 for a single enterprise domain is roughly one to three weeks of combined SEO, legal and development time. That is a planning range, not a benchmark. The gain is mostly risk reduction, clearer evidence and fewer unpleasant surprises, not extra traffic.
Next Step
If you are an SEO Manager, Head of Digital or VP who got this question from legal or the C-suite last week, do not answer it from a blog post (including this one). Start with the Knowledge Exposure Audit, or contact me and we will map what is exposed, what is cited and what needs a decision.
Frequently Asked Questions
Not settled. The U.S. Copyright Office says fair use must be judged case by case. Courts in two 2025 cases found training on lawfully acquired books to be fair use, but not the use of pirated copies. I could not verify a ruling that settles it for ordinary corporate web pages.
Partly. It is a request that well-behaved crawlers follow, not an enforcement tool. In the EU it is one of the signals that supports a rights reservation, and the GPAI Code of Practice commits signatories to respect it.
Under Article 4(3) of the DSM Copyright Directive, you can reserve your rights against commercial text and data mining. Article 53(1)(c) of the AI Act requires general-purpose AI providers to identify and respect such reservations, which should be machine-readable.
No. Training crawlers and search or retrieval crawlers do different jobs. Blocking everything protects rights on paper and removes you from AI answers in practice.
In the U.S., content generated entirely by AI cannot be registered for copyright, and the Supreme Court declined to review that rule on March 2, 2026. Human-authored contributions can be protected. Other countries, such as the UK, treat computer-generated works differently.
Not through the AI Act alone. Commentators note that third-party scrapers are not themselves bound by Article 53, so combine reservations, terms, technical controls and monitoring.
Limited today. I explain the options in my article on AI correction rights.
My working estimate is one to three weeks for a single enterprise domain, covering authorship records, terms, crawler rules and machine-readable signals. It is an estimate from my own work, not a benchmark.
This article was researched and drafted with the assistance of AI tools and reviewed and edited by author prior to publication.
