

In This Article
If your legal team just told you the company is “covered” because your servers sit in the right country, I have a question for you. Who checked what ChatGPT, Gemini or Perplexity actually say about your organization when someone in a different jurisdiction asks. Because that answer did not come from your servers. It came from a model trained on a mix of sources you never approved, hosted somewhere you probably never audited, and updated on a schedule you do not control.
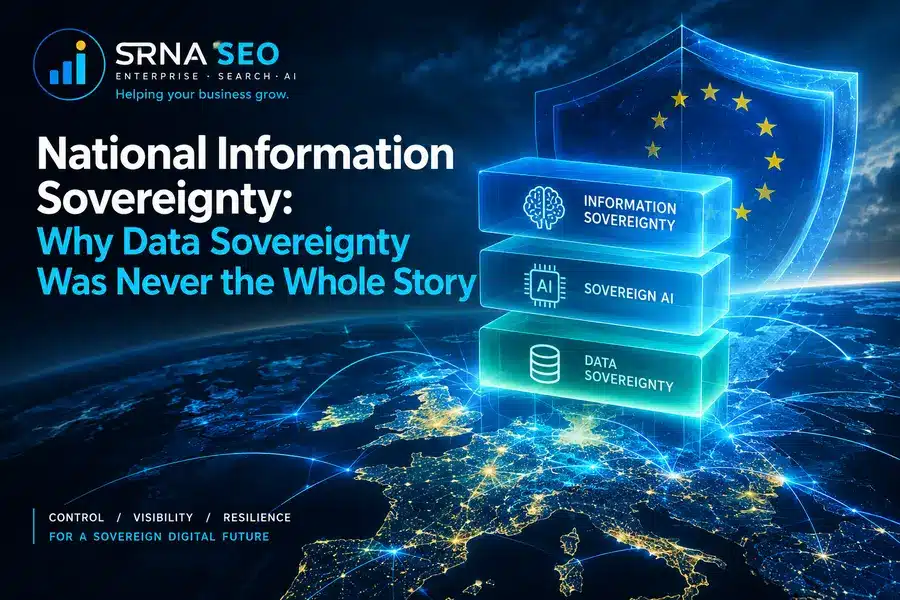
That gap is what I mean by national information sovereignty. Not where your data physically sits (that is data sovereignty, a narrower and much older idea). Not whether you own your AI infrastructure (that is sovereign AI, mostly an infrastructure and procurement question). National information sovereignty is whether a country, and by extension the organizations operating inside it, retain control over how their information is represented, retrieved, corrected and reused by AI systems that increasingly mediate what the rest of the world believes to be true about them.
A nation can have perfect data sovereignty and still lose control of its own information, because the AI layer sitting on top of that data answers to nobody’s jurisdiction in particular.
What national information sovereignty actually means
Most of what gets published under “sovereignty” right now stops at data residency. Where are the servers. Whose law applies if a government requests access. GDPR, the EU AI Act, and a dozen national data protection acts were built to answer exactly that question, and they do it reasonably well.
Information sovereignty sits one layer above. It asks what happens after the data leaves your infrastructure and gets absorbed into a training set, a retrieval index, or an agent’s context window. Once a large language model has ingested a fact about your country, your industry, or your company, that fact does not respect borders anymore. It gets synthesized, paraphrased, sometimes distorted, and served back to users in Toronto, Lagos or Seoul with no reference to where it originated or whose law should have governed it.
I saw a version of this problem from the inside, not in theory. During my time across global organizations like Adecco Group and Atlas Copco, cross border data flow was a constant negotiation between legal, IT and the business. Everyone understood data residency. Almost nobody at the table was asking who controls how the company gets described once an AI system has already learned about it. That question did not exist five years ago. It exists now, and most enterprises are answering it by accident, if at all.
The three layers, side by side
| Layer | What it controls | Who typically owns it | Where it usually breaks |
|---|---|---|---|
| Data sovereignty | Legal jurisdiction over stored and processed data | Legal, IT infrastructure | Cross border transfers, shadow cloud usage |
| Sovereign AI | Ownership of the compute, models and hosting stack | IT, procurement, national policy | Dependency on foreign hyperscalers |
| Information sovereignty | Accuracy, completeness and correction rights over how AI represents an entity | Nobody, structurally, unless someone claims it | Training data provenance, retrieval bias, no correction mechanism |
That third row is the one almost nobody owns inside a typical organization, and it is the one that decides what a prospective client, regulator, or journalist hears when they ask an AI system about you.
What this is not
National information sovereignty is not a rebrand of data localization. Forcing servers inside national borders does nothing if the model answering questions about your country was trained on a foreign dataset and hosted outside your reach entirely. It is also not the same as digital protectionism, blocking foreign platforms rarely improves how a nation’s information is represented, it just removes one more channel where correction was theoretically possible. And it is not a compliance checkbox you finish once. Models retrain, retrieval indexes refresh, and a correction you made in March can be quietly overwritten by September.
Why this became urgent, not theoretical
Three things converged over the past two years. AI answer engines replaced a meaningful share of informational search, which means the first (and sometimes only) impression a national institution, a regulator, or a company makes now happens inside a synthesized AI answer, not a list of ten blue links someone can cross check. Autonomous agents started acting on information without a human reading it first, which means a bad or outdated fact does not just mislead a person anymore, it can trigger an automated decision. And training data provenance stayed almost entirely opaque, so nobody, including most governments, can say with confidence which sources shaped what a frontier model believes about their country.
The uncomfortable truth is that most national AI strategies are still fighting the 2019 battle, infrastructure and data residency, while the actual battle moved to who gets to correct what a model says.
I wrote about the mechanics of this shift in the vulnerability of centralized data centers, and in the AI sovereignty framework I laid out the components a national strategy needs beyond infrastructure. If you are building this out at the organizational level rather than the national one, the sovereignty gap framework is the more practical starting point.
The components that actually make up information sovereignty
- Provenance visibility. Knowing, even approximately, which sources fed the model’s understanding of your entity. Rarely perfect, but the absence of any attempt is the real risk.
- Retrieval representation. How your organization or country shows up when an AI system answers a query that touches on you, even when nobody searched for you directly.
- Correction rights. A functioning path to challenge or update a wrong or outdated representation. I go deeper into this specific gap in AI correction rights for organizations, because right now this mechanism barely exists in any formal sense for most entities.
- Information supply chain integrity. The chain of sources, aggregators, and agents that a fact travels through before it reaches a model or an autonomous agent acting on your behalf. I mapped the mechanics of this in the AI information supply chain for autonomous agents.
- Exposure auditing. Actually checking what agents and AI crawlers can currently extract about you, which is the operational first step before any of the above matters. The agent exposure audit is built specifically for this.
Governments in the Global South are approaching this differently than the EU, largely because they are building the policy layer at the same time as the infrastructure layer, not after it. I covered that divergence in the Global South AI sovereignty framework, and the argument for why sovereign infrastructure alone is not a fiduciary substitute for this kind of control is in beyond the API, why sovereign stacks are the new fiduciary standard.
What this looks like inside Europe specifically
Europe has the most mature legal scaffolding for data sovereignty anywhere, GDPR did the heavy lifting a decade ago. But legal scaffolding for data does not automatically extend to AI representation. I am tracking this country by country in the Building a Europe AI Can See series, and the pattern repeats almost everywhere I look. Strong data protection law, close to zero formal mechanism for correcting how a national institution or a major employer gets described inside an AI answer.
This is not a small gap for enterprise organizations specifically. A misrepresented compliance status, an outdated regulatory claim, or a wrong attribution about who owns what, these things used to get corrected through a press office and a search engine reindex within days. Inside an AI retrieval layer, the correction cycle is unclear, sometimes measured in months, sometimes never.
What to actually do about it, honestly stated as a range
Based on the engagements I have run on knowledge exposure and AI visibility governance, organizations that run a structured exposure audit and put a correction and monitoring process in place typically see a meaningful reduction in factual drift within two to four AI answer cycles, roughly a 20 to 40 percent improvement in representation accuracy over the following two quarters. That range is honest, not a guarantee, and it depends heavily on how entangled the misinformation already is across sources.
If you cannot name who inside your organization owns the correction of how AI systems describe you, the honest answer is that nobody does, and that is the actual starting point of any information sovereignty strategy.
If you want a concrete first step rather than another framework to read, start with a knowledge exposure audit or run your own baseline through the AI Visibility Inspector. Both tell you what currently exists before you try to change any of it.
The part most vendors will not say out loud
Sovereign cloud contracts and national AI infrastructure investment are being sold, correctly, as a policy priority. But infrastructure ownership does not fix representation. A government can own every GPU inside its borders and still have zero say in how a foreign hosted model describes its institutions to the rest of the world. Information sovereignty is the piece that infrastructure spending alone cannot buy, and right now almost nobody is budgeting for it separately.
If your organization operates across multiple jurisdictions and needs a structured view of where representation risk actually sits, that is exactly the gap my advisory work closes, and it usually starts with a short assessment rather than a long engagement. You can request that through the enterprise search advisory or run a no commitment baseline through the AI Assessment Center.
FAQ
No. Data sovereignty governs where data is stored and whose law applies to it. Information sovereignty governs how that information, once absorbed by an AI system, gets represented, retrieved and corrected, regardless of where the underlying data physically sits.
Not on its own. Owning the compute and hosting stack controls where processing happens, not how a model represents an entity to the outside world. A nation can own its AI infrastructure completely and still have no correction mechanism for factual drift in how it is described.
Right now, structurally, nobody by default. It tends to sit unclaimed between legal, communications and whoever owns digital visibility, which is usually SEO or a search and AI visibility function. The organizations doing this well have named an explicit owner rather than assuming it falls under existing data governance.
Through repeated exposure audits comparing how an entity is represented across AI answer engines over time, tracking factual accuracy, completeness and whether prior corrections held. A single snapshot tells you almost nothing, the trend across cycles is what matters.
Partially. It addresses training data provenance obligations and some transparency requirements, but it does not yet establish a clear, enforceable correction right for how an entity is represented inside a model’s outputs. That gap is still open.
This article was researched and drafted with the assistance of AI tools and reviewed and edited by author prior to publication.
